Repository navigation
[WS1][CUDA][MiniMax-H3] ws1_one_h3_block + full-model qualification: block 0 node-by-node and 50-block/generation gates (RFC #420 stack 10/10) - #539
Conversation


|
Important Review skippedAuto reviews are disabled on base/target branches other than the default branch. Please check the settings in the CodeRabbit UI or the ⚙️ Run configuration
You can disable this status message by setting the Use the checkbox below for a quick retry:
Comment |

 Flink-ddd
added
platform: cuda
fusheng-ji
changed the title
fusheng-ji
changed the title
…frozen bounds, ensemble rule, candidate check, preflight)

…block 0 node-by-node and 50-block/generation gates

Squashes the one-block branch (its row-by-row history: timestep sinusoid, RMSNorm, AdaLN rows,
sequence/tensor parallel norm rows, final AdaLN, one block, 50-block qualification) onto the current
test-h3 so the pull request carries a reviewable, signed history. RFC RL-Align#420.

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
58e0821 to
17d0e9e
Compare
RL-Align#543.

539a–c minimax_h3 logs (4-GPU + SGLang overlay) and 543a–c qn/sm90 logs with tests.json, SHA256SUMS, and redaction metadata.
… and diagnostics (RFC RL-Align#420, RL-Align#539 split 1/3)

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
…e rule and reference manifest (RFC RL-Align#420, RL-Align#539 split 2/3)

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
…and resume check (RFC RL-Align#420, RL-Align#539 split 3/3)

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
…3f079/5ecb92de/6fe346df).

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
RL-Align#543

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>

|
Superseded by a stack of three PRs so that each layer is at most 10,000 lines of its own diff: #586 (block 0 replay and diagnostics), #587 (full-model qualification) and #588 (generation gate). The top layer has the same tree as this PR's head 17d0e9e, except nine Closing; please review the new PRs. The branch of this PR ( |


What
RFC #420 row
ws1_one_h3_block: one real H3 block, forward and backward, with every intermediate and a first-drift report.MiniMax-H3@42ed227runs as a 17-node graph, from the AdaLN projection to the second gated residual. It runs on packed FL2VA layouts whoseposition_idsand tags are bitwise equal to the pinned diffusers pipeline'sbuild_packed_sequence; the hashes are pinned in a CPU test.first_{,isolated_,repeat_,batch_}drift.temband all 12 block parameters (repeat, error vs golden);first_grad_{repeat,batch}_drift.block_tensors). They are extracted byprepare_h3_weights.py --blockfrom the same shard, so the existing conditioning file is unchanged.Bindings
adaln_projectionadaln_projection_3modnorm1,norm2h3_rmsnormresidual_attn,residual_mlpadaln_gate_residualq/k/v_proj,o_proj,ffn_gate_up,ffn_downh3_qkv_gemm,h3_attention_o_gemm,h3_ffn_gate_up_gemm,h3_ffn_down_gemmq_norm,k_normh3_qk_rmsnorm_d128H3RMSNormCudaOpon the 128-wide heads (bitwise equal tonn.RMSNorm)rope_q,rope_kh3_mm_rope_3axis_partialattentionh3_full_attentionDeterministicAttentionOp(causal=False)swigluh3_swigluSwiGLUCudaOpWhen an owning row lands, swapping its node's
candidatecallable is the whole integration, and the report entries become that operator's block-level evidence.Full-model and generation qualification (added 2026-10-12; numerical acceptance passed, three-seed generation quality not passed, see Status). This part covers the WS1 closeout rows
ws1_full_h3_transformerandws1_dual_trajectory, which are not claimed yet; it reuses the block graph above for every layer.tools.validation.models.h3_full_modelruns the real 50 transformer blocks, both text-refiner layers and the input/conditioning/output components. Each candidate block binds its own parameters to the block-0 graph, and the row/interim/reference labels are kept. Every parameter and input gradient is checked.examples/models/minimax_h3/full-model-thresholds.json, and a 1,635-file SHA-256 reference inventory.generation-contract.json: the pinned public reference image and prompt, seeds 42/43/44, 124 frames, 1344×768, 24 fps with joint 32 kHz audio. The comparator checks identical initial noise and shapes and reports PSNR/SSIM, temporal RMSE and audio differences.h3_generation_resume.py; recomputing the last saved step and requiring a bitwise match is opt-in; see Status).Prior art & reuse decision
This is a validation closeout, not a new kernel; no operator is written here.
MiniMaxH3TransformerBlockis the executable reference. It is replayed op for op as the provider (h3_provider), which pins its dtypes and op order without importing diffusers.rl_engine/validation/models/chain_gate.py). Its method is reused: per-node digests and first drift in graph order. Its graph is Qwen3's (causal, no AdaLN, Qwen shapes), so the H3 block is built on theh3_chainstage pattern of [WS1][CUDA][MiniMax-H3] timestep_sinusoid_h3: FP32 timestep features + shared H3 harness (RFC #420 stack 1/10) #483.TritonDetGemmOp.__call__reduces K as a tree with BF16 nodes; its FP32-accumulate kernel is equally deterministic and row-invariant, matches cuBLAS's accuracy, and is 9–17× faster (B200, error vs FP64):Direct bitwise comparison
The H3 block is composed of the WS1 rows below it, and their reuse candidates are compared byte for byte with
tools/validation/models/h3_bitwise_reuse.py(committed in #483, merged down the stack). It runs every candidate thath3_prior_art.candidates()defines on identical inputs and compares every output and leaf gradient with diffusers' path and with the rl-kernel op. Each row's report, written from a clean tree on its own branch: #483timestep_sinusoid; #484timestep_mlp; #485adaln_projection; #486adaln_row_gather; #487norm_modulate; #488gate_residual; #489final_adaln_out.Results
Block-0 replay, generated from a clean tree at
41e4293on an otherwise idle B200 (torch 2.13.0+cu130), withtools/validation/models/h3_block_replay.py --layouts tiny,small,medium:report.json.adaln_projection/adaln_projectionadaln_projection/adaln_projectionadaln_projection/adaln_projectionnorm1/norm2,q_norm/k_norm, RoPE, and both gated residuals. The first drift is the first reduction whose tree differs from cuBLAS.adaln_proj.weight,adaln_proj.biasandtemb. diffusers'index_selectbackward accumulates in BF16 atomics; the row operators use FP32 segment sums.attn.norm_q.weightat S = 3160 (9.5e-3 vs 5.5e-3). At S = 925 the same leaf is 2× more accurate than diffusers, so the 128-element gradient's error follows BF16 rounding, not one side.h3_full_attention.Full-model qualification
Gates of
candidate.sbatchatc249a735on one B200 (torch 2.9.1+cu130) against the regenerated reference, from a clean checkout; generation from clean checkouts at4792c8a9/2451ae5c(same model code, see Status). Evidence: README, acceptance, comparison, generation quality, provider variants, first-step replay, provider spread.adaln_proj.linear.weight)max_absonly, 2 also on relative_l2Generation quality per seed (bounds: PSNR ≥ 30 dB, SSIM ≥ 0.99, temporal RMSE ≤ 0.01, audio relative L2 ≤ 0.05; a failing value is bold):
The same bounds applied to the provider with one SDPA backend forced on the transformer (same seeds, inputs and conditioning):
First denoising step replayed from its saved packed inputs (nothing has fed back yet), relative L2 of the video output against the provider's saved step (replaying the provider is bitwise equal to it):
Status
c249a735against the regenerated reference).2681cadb). 1,614 of the 1,635 pinned files are byte-identical to the first run's; the others are the eightreport.jsonfiles, the thresholds file that embeds their hashes and twelvevideo.mp4/audio.wavcontainers, which also differ between two runs of one job. The calibrated bounds and the ensemble rule re-derived from the regenerated reference are identical in every numeric field; the manifest, thresholds and rule are re-pinned to it (c249a735) and the first run's hashes are in the model README.max_abs(1 on relative_l2), cuBLASLt 38 (3), memory-efficient attention 66 (9), while the default configuration they were calibrated on fails none.max_abs, which is set by one element, is reported but not gated: held-out providers exceed the others' maximum by up to 4.1× on it.41e4293/caaf754(Results) has no known failures.58e08219. The DCO check reports a failure because it cannot read more than 250 commits; every non-merge commit on this branch (284 commits in all, 130 of them non-merge) carriesSigned-off-by(checked withgit log).test_h3_adaln_modulation.py::TestFusedModulation::test_backward_keeps_table_gradient_fp32in [WS1][CUDA][MiniMax-H3] adaln_row_gather: fused six-way AdaLN row gather (RFC #420 stack 4/10) #486 (62f8009e), merged here. Its golden rounded an FP64 SiLU where the kernel rounds the FP32 SiLU, andtembwas unseeded; the kernel was deterministic.History
8324ec69,8493d5ba,9951ddab,ebd0512b).h3_first_step_diagnostic.pyreplays the first denoising step from its saved packed inputs under a given configuration (the provider, optionally with one forced kernel; the candidate; the candidate with chosen block nodes run as the provider's). Replaying the provider default reproduces the saved step bitwise on all three seeds, which validates the replay.h3_full_generation --provider-variantgenerates the provider's videos with one SDPA backend forced. The first attempt forced it around the whole pipeline, so the Qwen3-VL text encoder crashed under memory-efficient attention and would have had its text embeddings changed under flash attention; it now applies to the transformer's forward only, and the first attempt's outputs were discarded.h3-full-model-b200/onpr_assets.generation-compare.sbatchdid not put the dependency overlay (scikit-image) onPYTHONPATH; fixed infcd4ed27and rerun.1a7a2fc1,2451ae5c,c249a735).--verify-last-step(opt-in; it was checked across nodes on the first run).MODEL_PATHS), not a commit, so a commit that changes only orchestration code can continue it;h3_generation_adopt.pymoves an older commit-based run over, only if those paths are byte-identical (checked for all seeds before any is changed).generation.sbatchaccepts the numerical gates by the same identity. The 57 steps saved at4792c8a9(18, 19 and 20 for seeds 42, 43 and 44) were adopted this way, which is why seeds 42 to 44 carry steps computed under two commits with identical model paths.1a7a2fc1(preflight size): a resume with nothing left to compute and the opt-in verification both reproduce the uninterrupted run byte for byte.c249a735); see Status.db8c69c7,026fd60e,4792c8a9,f4e9a37f; revised below).h3_full_generationtakes--seedsand--resume. Each saved step has a sidecar with the digest of the transformer's inputs and of the saved file, written atomically. On resume the saved transformer calls are replayed from disk and the pipeline's own scheduler turns them into the next latents; every replayed call's input digest is checked. A run directory is tied to the commit, contract, seed and settings it started with (revised below).candidate.sbatchends after the numerical gates and the preflight;generation.sbatchruns one seed per array task and refuses to start unless those gates passed;generation-compare.sbatchcompares afterwards.forwardsignature from the pipeline (fixed in4792c8a9, with two tests that fail without the fix);f4e9a37ffixes a mypy error that CI found in the new module.3fc8f93a,c8ac5b19,9b1e3ee7,6e114f9c,48f60361):--provider-variantand--provider-nodeson the full-model runner,h3_full_provider_spread.py,h3_full_ensemble_rule.pyand the frozenfull-model-ensemble-rule.json. A candidate run ata7d3f9d0completed the full-model forward/backward and failed 54 of 764 single-configuration bounds, so generation did not start; see Status for what followed.5e5df82f,a7d3f9d0), after a candidate run at98b07a3fstopped at the block-0 gate (8 passed, 1 failed: theattn.norm_q.weightgradient's relative error 0.03398705939217804 against the bound 0.03044327425907444, provider 0.016962182839382958). With identical inputs and upstream gradients the isolated Q/K norm errors of candidate and provider are equal (Q 0.0016656962, K 0.0029305728), so the difference comes from upstream.2681cadb): FP32/BF16 provider passes over all 50 blocks, both refiners and the boundaries, with 638 parameter-gradient artifacts per precision. Reference generation and repeats passed for seeds 42/43/44 at 124 frames, 1344×768, 24 fps and 32 kHz audio, and all 49 predicted-velocity steps matched their repeated provider controls. These are provider results.KERNEL_ALIGN_USE_FAST_MATH=1adds--use_fast_mathto the whole_Cbuild, which approximatesexpf/sinf/cosf/rsqrtf/division and flushes denormals. Before the fix a fast-math build of the top of the stack failed 33 H3 tests (thetimestep_sinusoid_h3andh3_rmsnormbitwise tests and the chain/block tests built on them;det_linear,adaln_row_gatherandgate_residualstill passed). Everycsrc/cuda/h3source is now inH3_BITWISE_SOURCESand left out of fast-math builds, the bindings are gated onKERNEL_ALIGN_WITH_H3_KERNELS, and dispatch falls back to the PyTorch references. On this branch: merge4ba3a8fband9cb10d03(block dispatch-check skip). Results for both builds are under Tests.0348e37b). The.sbatchscripts keep only site-neutral resource requests (site-specific scheduler options are given at submission), the reference manifest isreference-manifest.jsonwithout a job ID (its 1,635 file hashes are unchanged, so the reference evidence still verifies), andgeneration-inputs.jsonrecords the source suite relative to its pinned revision.9317a5e1). 14 report links outside the MkDocs tree now point to immutable GitHub URLs at68e472b7; the strict docs build passes. No evidence or numbers changed.ae620486onward; see What). An earlier reference attempt completed its backward stages but failed generation because torchvision/the video processor was missing; the processor repair and a matching torchvision overlay fixed the rerun. Earlier local expanded CPU results (149 passed, 358 hardware skips, three subprocess-startup timeouts) are historical, not an all-pass claim.03cd824b). The one-blockreport.jsonandfigure.pngmoved toreports/experiments/h3-one-block-b200/(now onpr_assets:h3-one-block-b200/) with identical SHA-256; the report keeps its41e4293measurement revision. Docs, the plotting example and the layout audit map were updated; no GPU numbers were rerun.caaf754,tests/models/minimax_h3on 2× B200: 501 passed, 5 skipped; with the fast-math guard (2× B200, passed / skipped / failed): default 545 / 7 / 0, fast-math 196 / 356 / 0; after the flaky-test fix at27bb0295: default 550 passed / 7 skipped, fast-math 201 / 356, 0 failed; uniform cluster run at3bd2300a(8× B200): default 554 / 3 / 0, fast-math 201 / 356 / 0.Tests
At
ebd0512b(the head when this was measured;58e08219only moves the measurement outputs out of the PR and editsdocs/operators/), 2× B200, pinnedMiniMax-H3@42ed227weights including block 0; each build compiled from a clean checkout of that commit:_CKERNEL_ALIGN_USE_FAST_MATH=1Default-build skips (7): 4 need 4 or 8 GPUs (the tensor- and sequence-parallel NCCL tests, on a 2-GPU host); 3 depend on the environment only (matplotlib, SGLang's JIT, CI-only extension enforcement).
Fast-math regression tests:
tests/build/test_build_platform_collectives.py::test_cuda_build_compiles_h3_kernels_without_fast_math,::test_fast_math_build_excludes_bitwise_h3_kernels,tests/runtime/test_dispatch.py::test_h3_timestep_falls_back_when_fast_math_build_omits_kernel,::test_h3_ops_prefer_cuda_and_fall_back_to_pytorch_reference.tests/models/minimax_h3/test_h3_one_block.pychecks the block-0 replay: on CPU, that the layouts are pinned to diffusers, the graph is well formed and MM-RoPE rotates 96 of 128 channels; on GPU forward (S = 264, 925), that every node repeats and is batch-row bitwise, promised nodes are isolated-bitwise and node and output errors are at most 1.25 × diffusers' + 1e-3; on GPU backward (S = 264), that every leaf repeats, dX is batch-row bitwise, no gradient drifts and leaf errors are at most 1.5 × diffusers' + 5e-3, or, for a BF16 leaf, at most 6 ulps above diffusers'.tests/models/minimax_h3/test_h3_generation_resume.py(22 CPU tests, included in the counts above) drives a fake denoising loop through the same resume code: a run preempted once or repeatedly equals an uninterrupted one, nothing is recomputed by default, the opt-in verification catches a drifting recompute, other identities, corrupted files and signature changes are rejected, and adopting a commit-based run is tested against a real temporary git repository. The real-pipeline checks are described in History.On this PR the GitHub checks are DCO (see Status), CodeRabbit, lint, the CPU unit tests and docs.
Scope / Known limitations
h3_mm_rope_3axis_partiallands.tembis the provider's (the conditioning chain is [WS1][CUDA][MiniMax-H3] timestep_sinusoid_h3: FP32 timestep features + shared H3 harness (RFC #420 stack 1/10) #483–[WS1][CUDA][MiniMax-H3] adaln_row_gather: fused six-way AdaLN row gather (RFC #420 stack 4/10) #486).h3_full_attentionis the row that would remove it. The generation environment needs torchvision matching PyTorch, andQwen3VLProcessorneeds its video processor even for image conditioning.max_absis reported); it and the block-0 ulp allowance rest on measured provider spread and were designed after the candidate had failed the earlier bounds. The generation quality bounds were not changed (see Status).Results (H100 / Hopper)
Measured on 4 x NVIDIA H100 80GB (sm90), driver 580, CUDA 13.0.88, torch 2.13.0+cu130, pinned
MiniMax-H3@42ed227, clean tree at58e08219. Evidence files live on thepr_assetsbranch underpr539/reports/experiments/*-h100/.Tests (
pytest tests/models/minimax_h3 tests/build tests/runtime/test_dispatch.py)KERNEL_ALIGN_USE_FAST_MATH=1build: 224 passed, 355 skipped in 49.38s (the fast-math build omits the H3 CUDA sources to keep bitwise parity, so H3 CUDA tests skip there)Scope: block-0
h3_block_replay --layouts tiny,small,medium, the full 50-block model qualification (below), and a one-step generation preflight. The three-seed generation gates (about 20 h per seed) were not run on this machine.Figures
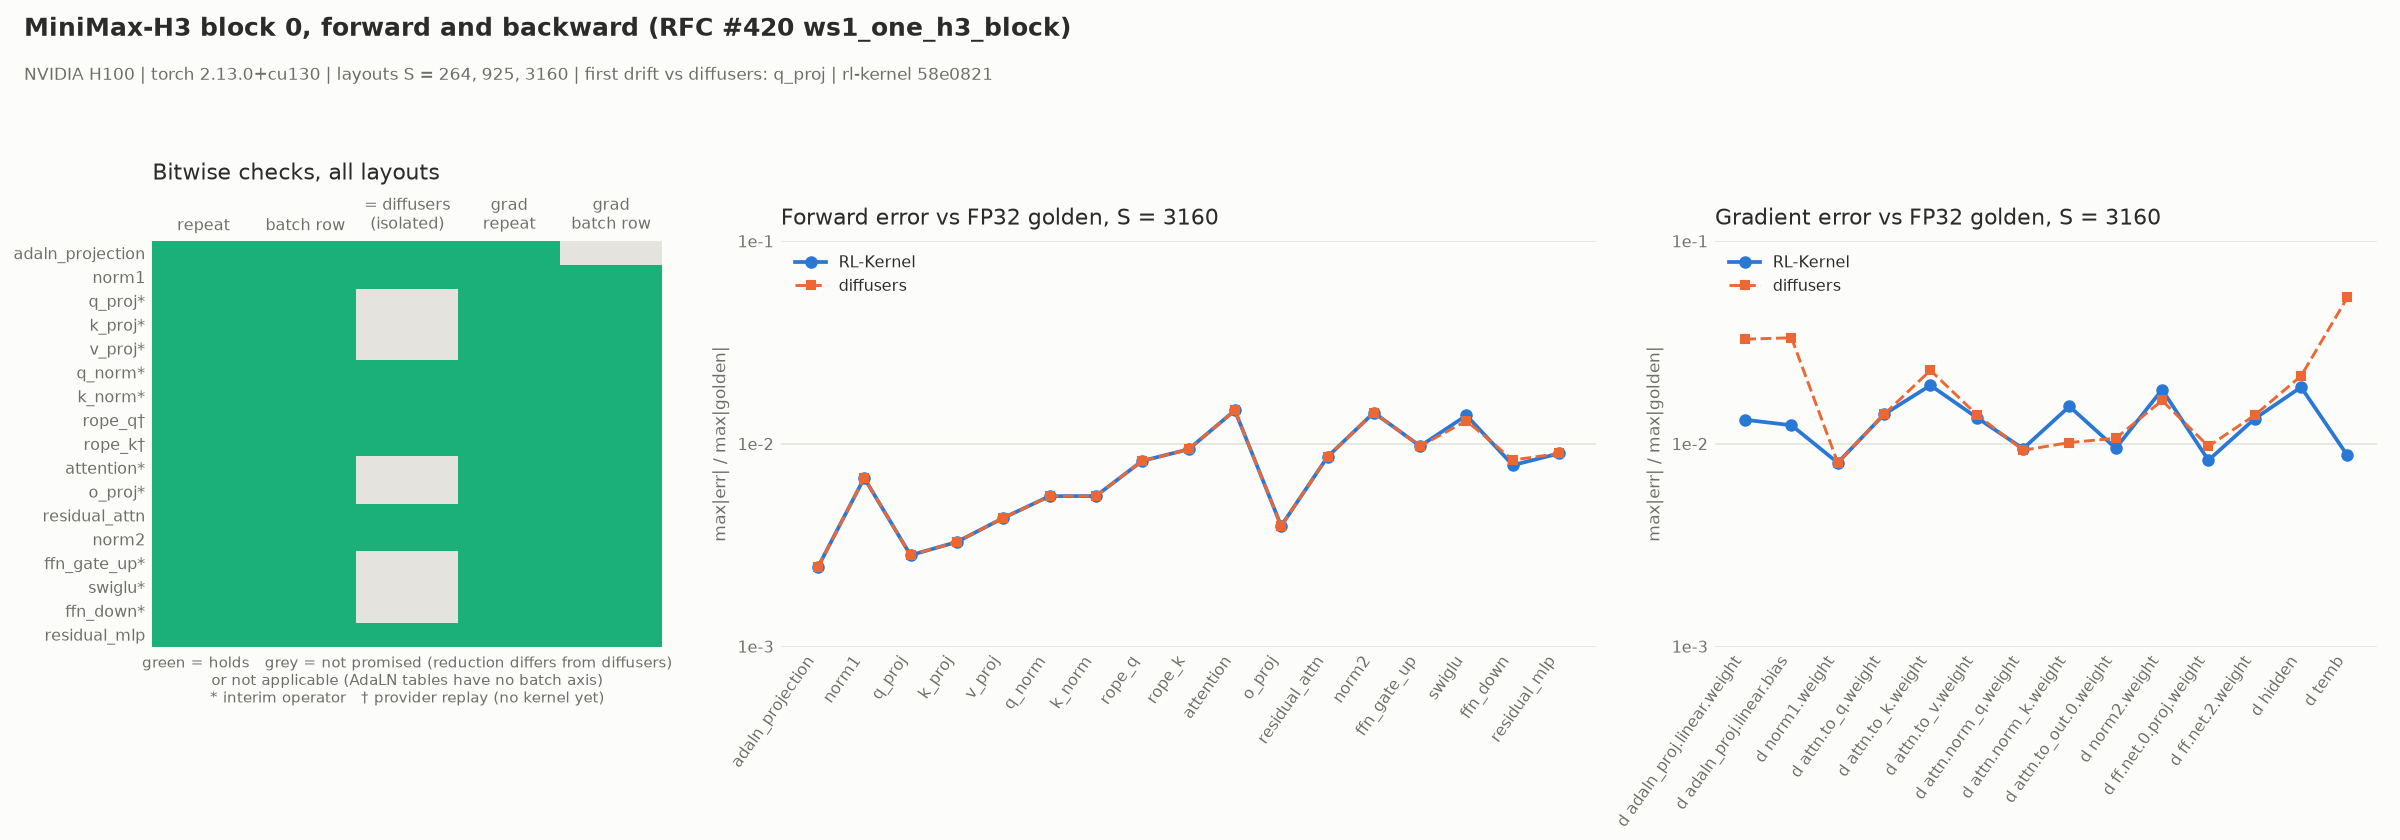
Full 50-block model on H100 (one packed FL2VA sample, forward plus complete backward, 638 parameter gradients; files under
pr539/h100-full-model/on thepr_assetsbranch, commit23cc7e28)All references and bounds were re-measured on H100: FP32 reference plus four BF16 providers (default, sdpa-flash, sdpa-efficient, cuBLASLt).
nodes.block.33The single-provider bound is not the acceptance criterion here, for these reasons: