Repository navigation
[WS1][Qwen-Image][CUDA] AdaLN modulation projection (adaln_mod_projection) - #537
fusheng-ji wants to merge 3 commits into
Conversation


Add the Qwen-Image Phase A `adaln_mod_projection` operator (RFC RL-Align#386):
per-stream SiLU + Linear 3072->18432 with a fixed-order FP32 forward,
compensated input gradients and ascending FP32 Neumaier parameter
gradients, plus an independent CPU FP32 reference.

Sources live under csrc/cuda/model_specific/qwenimage,
rl_engine/backends/cuda/model_specific/qwenimage and
rl_engine/reference/model_specific/qwenimage. Register the CUDA and CPU
slots (other platforms fail closed), the native bindings, the WS1
operator spec/inputs and the build source, and add tests, evidence
runners under benchmarks/models/qwenimage, and the operator page.

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>


|
Important Review skippedAuto reviews are disabled on base/target branches other than the default branch. Please check the settings in the CodeRabbit UI or the
 |
 Flink-ddd
added
platform: cuda
The raw results (JSON, figures, audit files) now live on the fork's pr_assets branch;
the documents link to them at a fixed commit.

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
e6cebf0 to
ba27aee
Compare
…, PR RL-Align#538 FlashInfer DiT LayerNorm attempt

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
ba27aee to
a73c66c
Compare
…Align#491 RL-Align#537 RL-Align#538 RL-Align#536 RL-Align#547.

Redacted logs, JSON, and summaries under pr<N>/hopper/.

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>

| #include <cstdint> | ||
| #include <vector> | ||
|
|
||
| bool qwenimage_strict_math_compiled() { |

There was a problem hiding this comment.
FAST_MATH doesn't reliably detect NVCC's --use_fast_math, so this can incorrectly report a strict build. Please enforce this in the build configuration and test an actual fast-math build; the current test only mocks the result.
There was a problem hiding this comment.
Thanks, you are right: nvcc defines neither __FAST_MATH__ nor __USE_FAST_MATH__ for device code (I checked with CUDA 13 and --use_fast_math), so the old check always reported a strict build. Fixed in 274b6c5: qwenimage_strict_math_compiled() now runs a small probe kernel in the same translation unit, so it sees the real flags. It checks that a subnormal survives a multiply and that one division matches IEEE, and both change under --use_fast_math. The new tests/models/qwenimage/test_strict_math_build.py compiles the real det_linear.cu with and without --use_fast_math and asserts False/True.
…plicitly

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>

|
🔍 OpenCodeReview found 9 issue(s) in this PR.
📄
|


|
@fusheng-ji The automated OCR review has completed. Please review and address all automated review bot findings, then push your updates. Maintainers will begin manual review after the bot findings have been addressed. |


What
RFC #386 WS1 row
adaln_mod_projection: the per-stream modulation projectionSiLU(temb) @ Wᵀ + b, 3072 → 18432, run separately forimg_mod.1andtxt_mod.1, with forward and backward.mma.syncK=16 partials summed in a fixed order. Neither depends on B or on a row's batch position.d_weightuses an ascending FP32 Neumaier sum of products and their FMA residuals;d_biasuses an ascending Neumaier sum. Only the final result is cast.rl_engine/reference/model_specific/qwenimage/).qwenimage_adaln_mod_projection: CUDA slot only, no fallback; CPU maps to the reference; ROCm/NPU/MUSA fail closed. WS1 operator spec and inputs, binding, build source, anddocs/operators/qwenimage-adaln-mod-projection.md.Placement. The sources are under
csrc/cuda/model_specific/qwenimage/,rl_engine/backends/cuda/model_specific/qwenimage/andrl_engine/reference/model_specific/qwenimage/, following the repository layout guide'sbackends/<platform>/model_specific/<model>/convention for operators that depend on one model. The contract is Qwen-Image-specific: fixed 3072 → 18432 shape,(shift, scale, gate) × 2chunk order, model-qualified registry key. If you prefer the operator-family layout used by #499 (gemm/), I can move it.The
final_adaln_outrow builds on this projection and follows as a stacked PR.Prior art & reuse decision
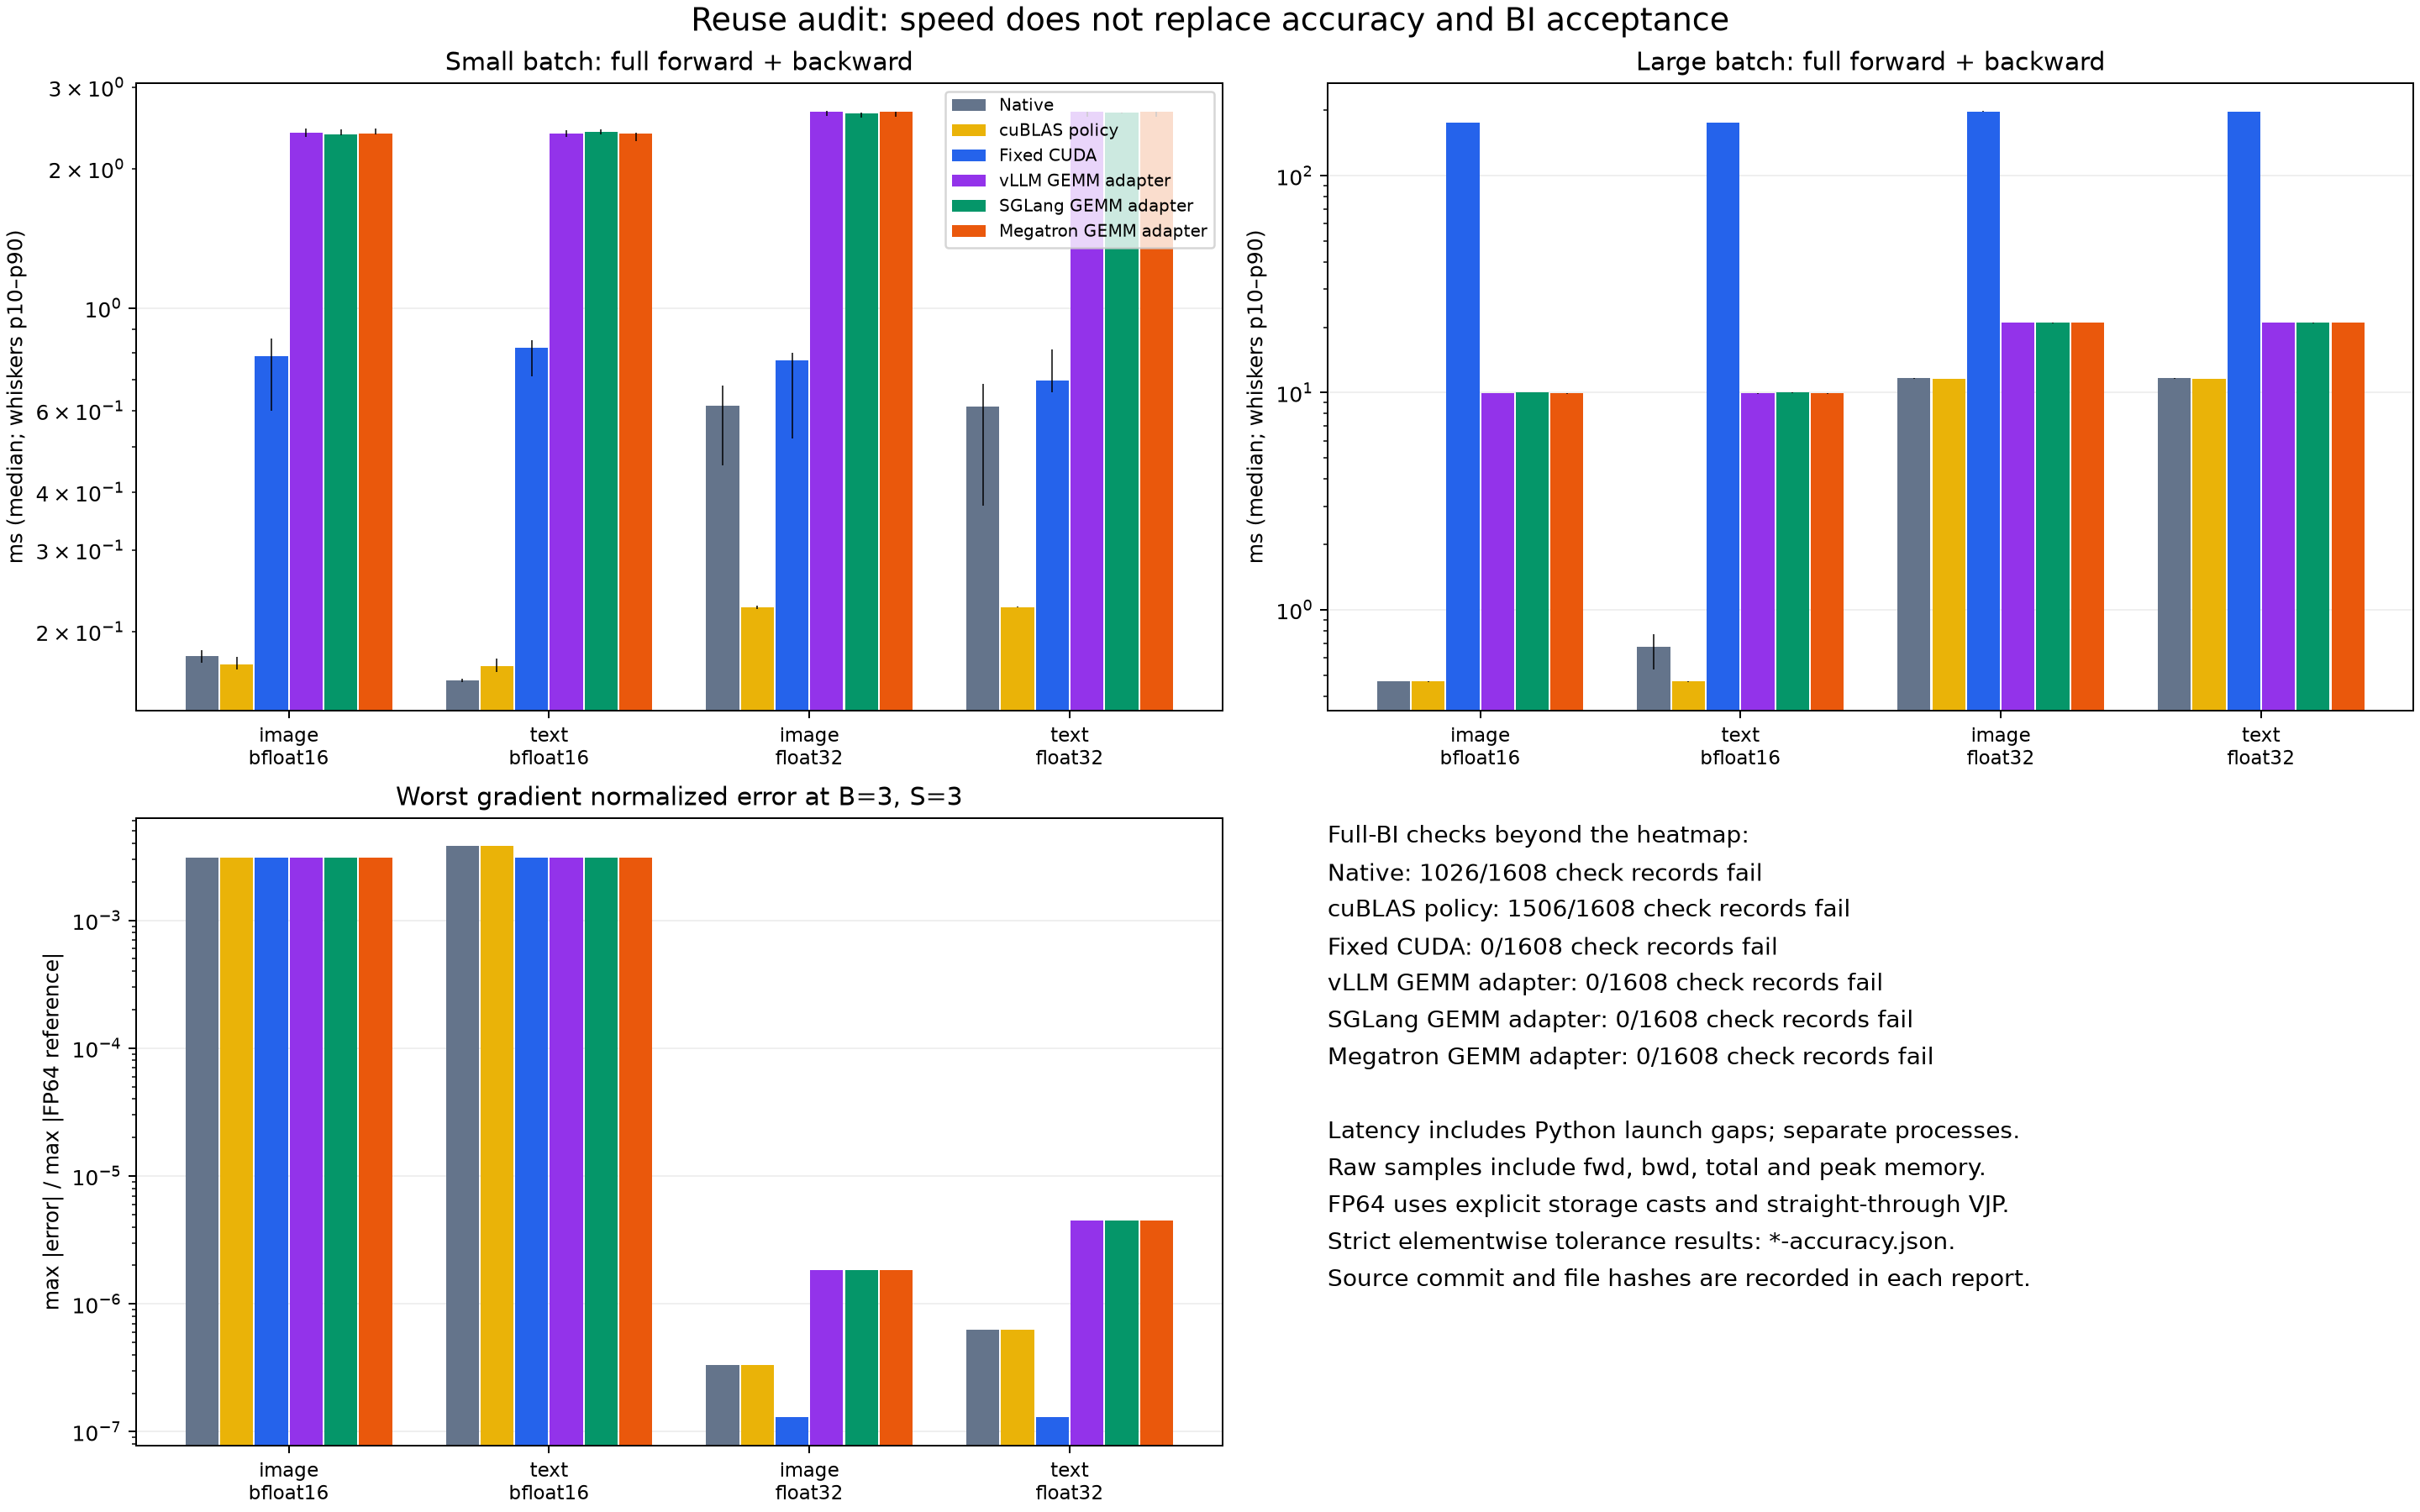
Every candidate was measured on the full forward and backward path with the checkpoint's block-0 weights, on the same harness as this kernel (
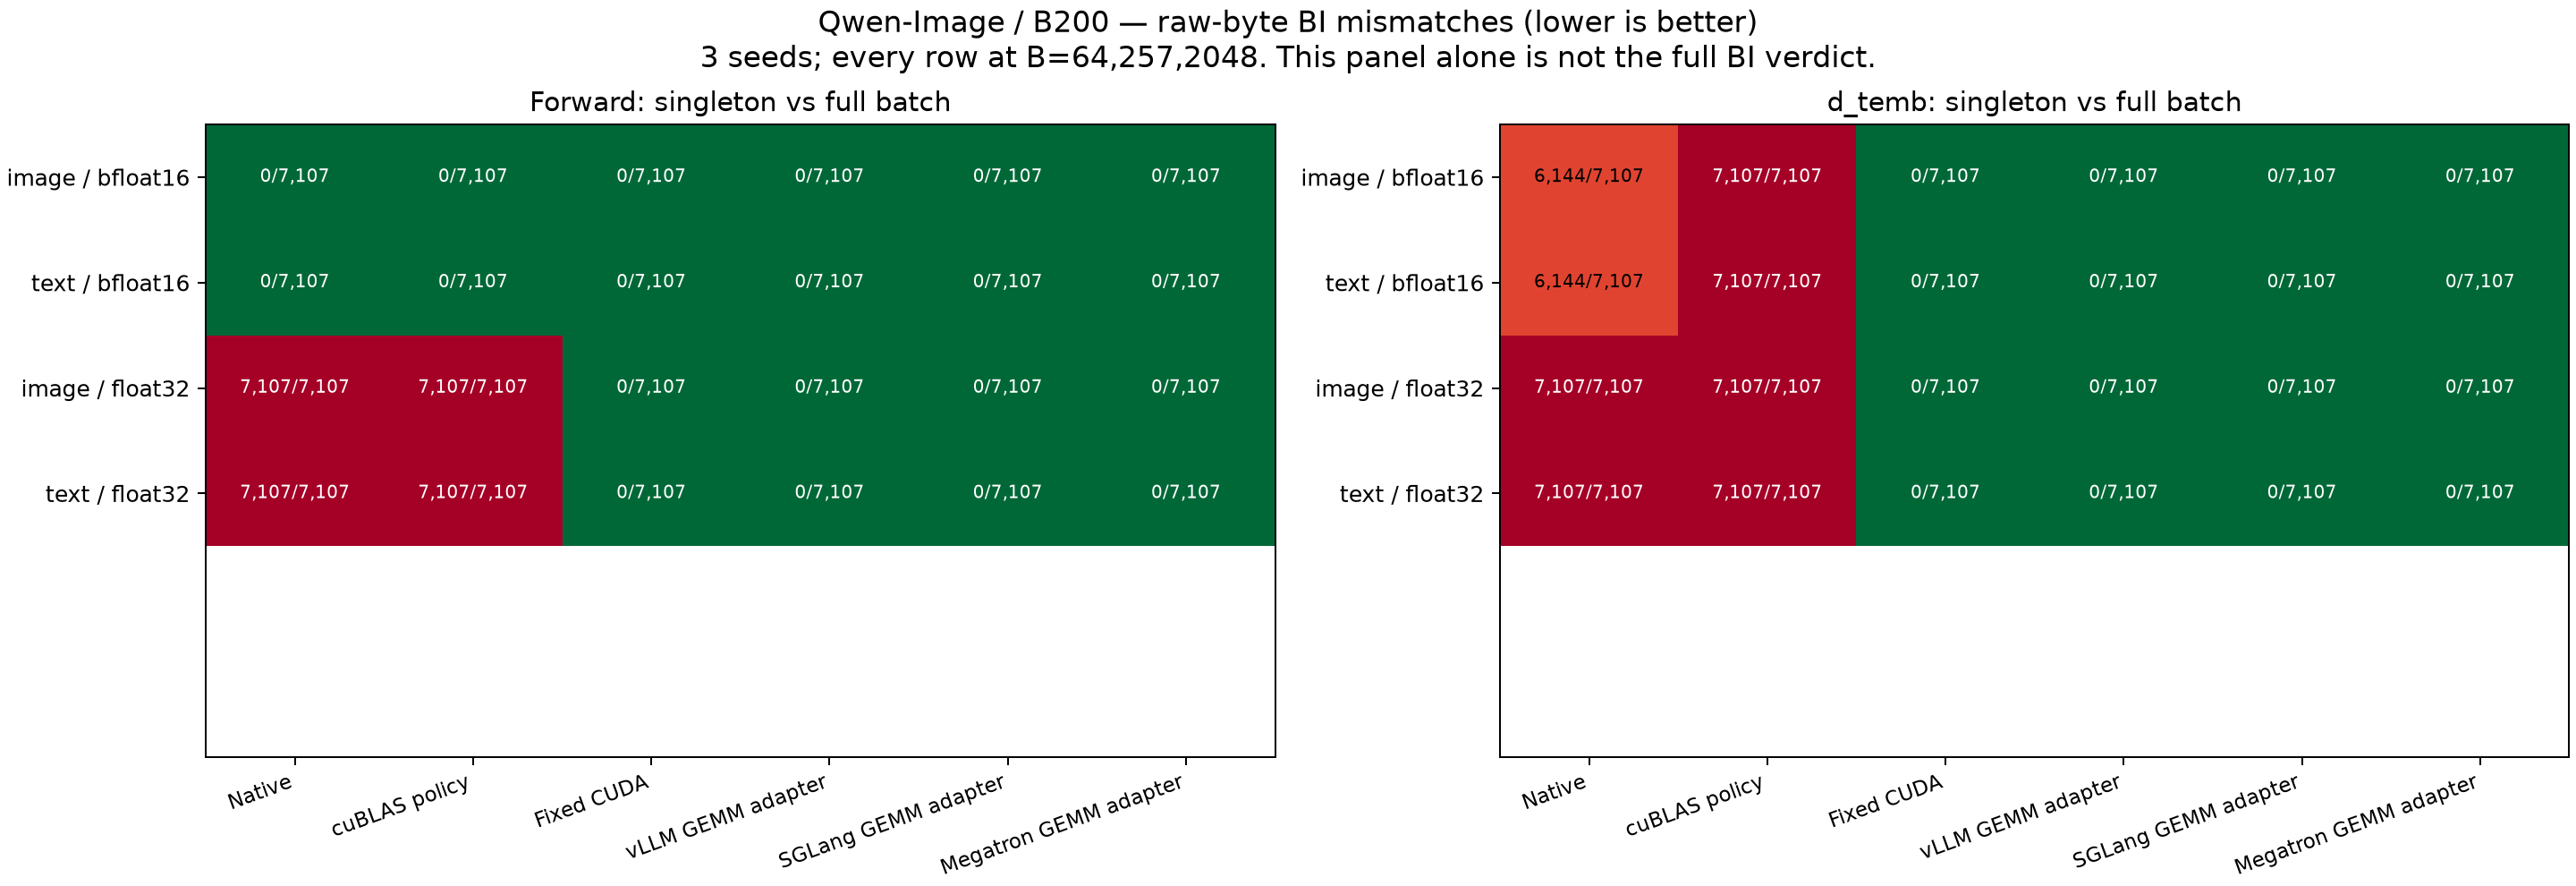
benchmarks/models/qwenimage/adaln_reuse_bi_audit.py). BI is checked bytewise: a singleton vs every row of B = 64/257/2048, three seeds, dense and power-of-two-boundary batch sweeps, row position and reversal, and the full 4096-sample workload in 5 chunkings.F.silu+F.linear(cuBLAS), torch 2.13.0+cu130--mode native --phase bi: 1026/1608 records fail, 26502/28428 singletond_tembrows differvllm/model_executor/layers/batch_invariant.py@7797b60(vendored asbenchmarks/layers/vllm_batch_invariant_matmul.py)--mode vllm_local --phase bi: 0/1608d_weight2 elements/stream over toleranceCUBLAS_WORKSPACE_CONFIG=:16:8,CUBLASLT_WORKSPACE_SIZE=1--mode cublas_policy --phase bi: 1506/1608 failsglang/srt/batch_invariant_ops/batch_invariant_ops.py, sglang 0.5.21--mode sglang_local --phase bi: 0/1608d_weightfailuremegatron/core/transformer/custom_layers/batch_invariant_kernels.py@52fbcbc--mode megatron_local --phase bi: 0/1608d_weightfailure0b55a2f: GEMM templates/examples onlySiLU + Linearoperator with a BI contract or autograd34bb66e: no batch-invariant linearflash_attn/ops/fused_dense.py@94e22c9: cuBLASLtfused_dense_lib, GELU/ReLU epilogueslinear_act_forward(GELU/ReLU epilogue, the only variants it has), singleton vs batch at in 3072 / out 6*3072, 3 seeds, B = 64/257/2048, torch 2.12.0+cu130 (the other rows use 2.13): GELU fails 9/9 records (e.g. 277 of 2048 rows differ at B = 2048), ReLU 0/9; probe. FP16/BF16 only, so the FP32 path cannot run1d367a4/05bd9cb/b9ecdf5:git grep -iE 'img_mod|txt_mod|AdaLayerNormContinuous|adaln'→ no filestransformer_qwenimage.py@d961a38:nn.SiLU+nn.LinearAccuracy at unchanged tolerances (
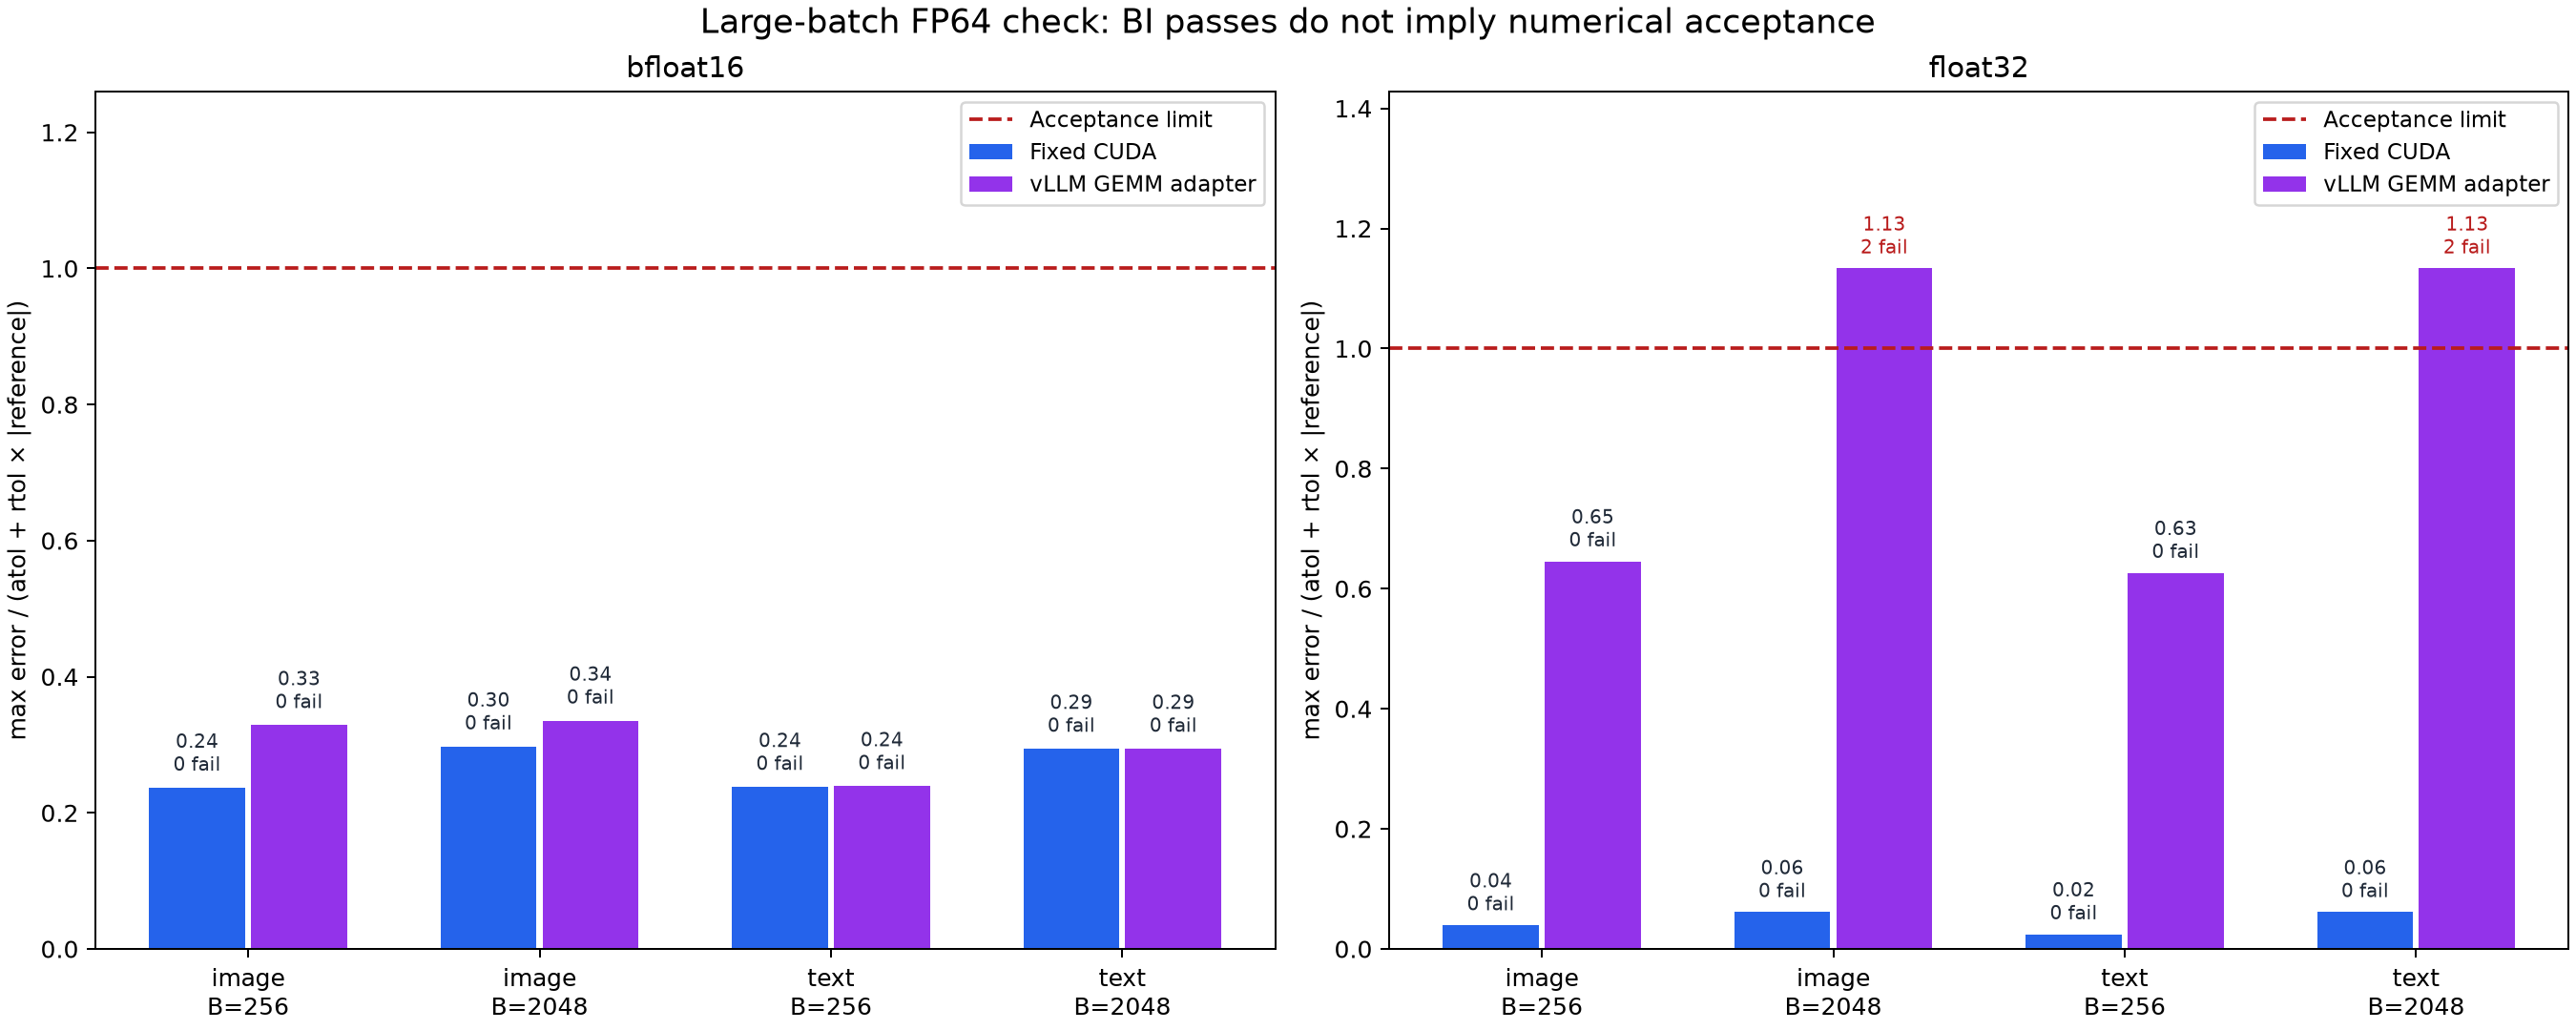
--phase accuracy/accuracy_large, FP64 reference): the three persistent GEMMs pass all BF16 cases and FP32 up to B = 256; at FP32 B = 2048, 2d_weightelements per stream exceed atol = rtol = 1e-4. This kernel has no failures.Image stream, forward + backward median ms:
Decision: I kept the kernel, but this is the maintainers' call (see Status below).
d_weightat B = 2048. The persistent GEMMs are forward-only, so reusing them still needs a training adapter like the one in this PR's audit. Qwen-Image conditioning batches (prompts × CFG branches) are small, where the kernel is faster.Rejected along the way (historical, code removed): a K=32 partial-dot reducer failed cancellation accuracy and changed bytes at the B = 256 dispatch boundary. An ordered-tile Neumaier reducer passed every numerical gate but was 17–26% slower than the fixed reducer.
Results
Measured at
c88f7c0fe35d6544e092a16097a094d323b35581. The evidence commit adds onlydocs/usage/evidence/qwenimage-adaln-mod-projection-b200/.fixed/acceptance.json is qualified with zero failures:
Accuracy (strict FP64 acceptance; this kernel vs the batch-invariant GEMMs):
Batch invariance (raw-byte mismatches per candidate):
Performance (forward + backward, all candidates; and this kernel vs native PyTorch at B=1):
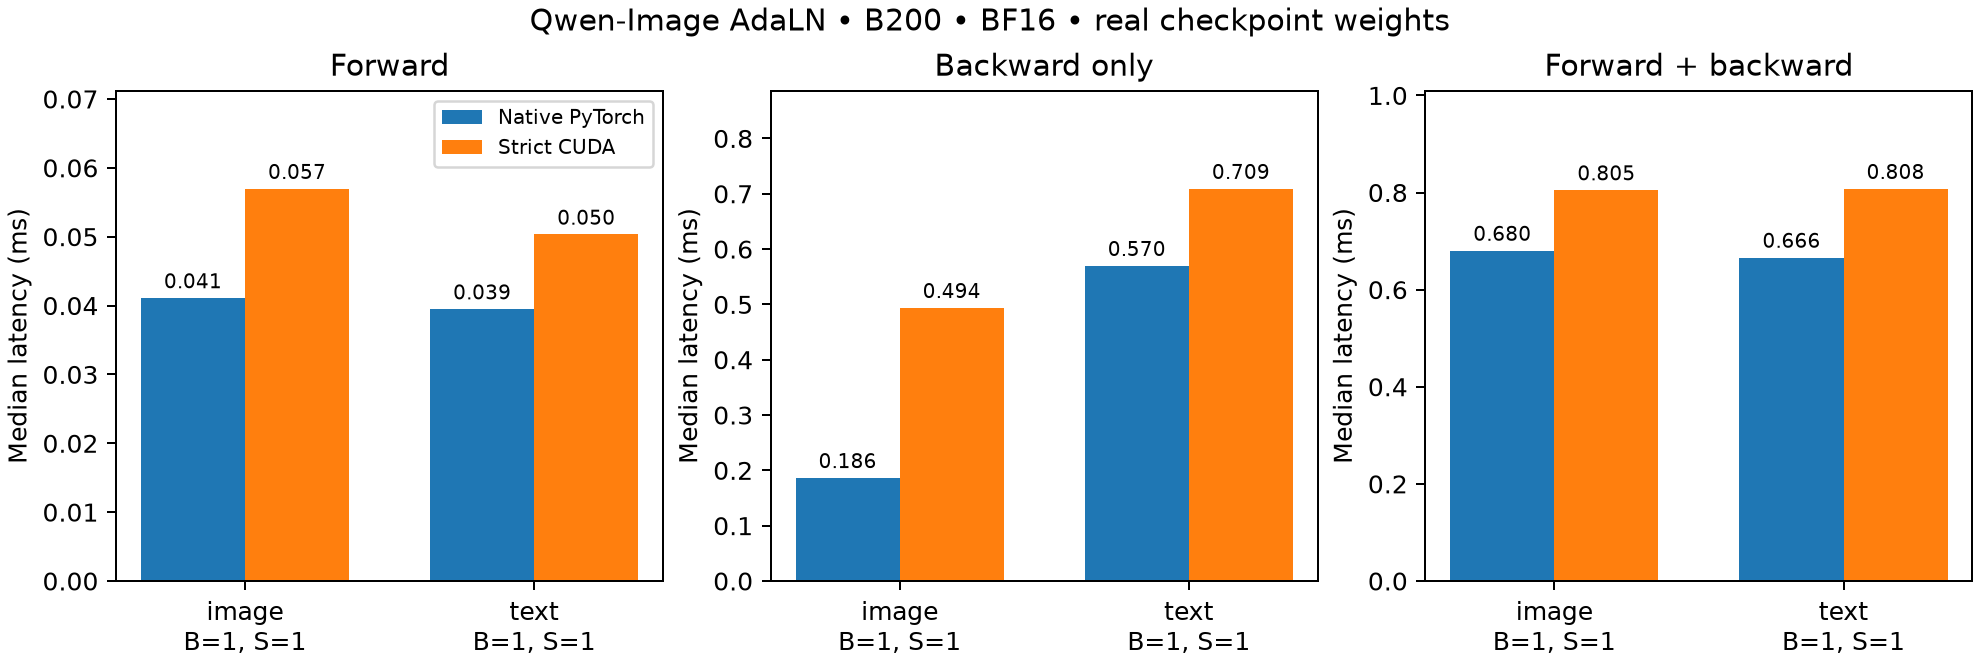
Peak memory at B=1 is 111.6 MiB vs 108.1 MiB for native PyTorch. Environment: B200 (SM100), PyTorch 2.13.0+cu130, CUDA 13.0, driver 580.126.20, TF32 off, no fast-math. Full evidence, pins and reproduction: README.
Results (H100 sm90, head
a73c66c5)Measured at
a73c66c5e2db7ec844e30ac763ce85d410179259on H100-94GB (SM90). Raw logs and JSON are onpr_assetsunderpr537/hopper/(commit42eb4190).fixed/acceptance.json is qualified with zero failures (1808 checks):
Within-H100 repeat/batch invariance only (BF16
mma.sync); raw bytes are not claimed equal to B200 (RFC #428 §2.2). Model: Qwen/Qwen-Image @75e0b4be04f60ec59a75f475837eced720f823b6. Environment: H100 (SM90), PyTorch 2.13.0+cu130, CUDA 13.0, driver 580.173.02, TF32 off,TORCH_CUDA_ARCH_LIST=9.0, no fast-math. Summary:SUMMARY.md,report.json,env_header.txt.Status
No known failures at
d0708cddd0587755b8fb77a211bce5d0f4df84a6. Evidence was produced from a clean checkout of the code commitc88f7c0fe35d6544e092a16097a094d323b35581, which is this PR's parent of the evidence commit.Open question for the maintainers: keep this kernel, or reuse a batch-invariant GEMM? vLLM's, SGLang's and Megatron's persistent GEMMs are batch-invariant for this projection, pass every BF16 case, and are 6–18× faster at B ≥ 256. They need an FP32 VJP adapter (the GEMMs are forward-only), and they exceed the FP32
d_weighttolerance at B = 2048 (2 elements per stream). This kernel passes every case and is 2.6–3.4× faster at B = 1–3. Details are in Prior art & reuse decision above.Tests
101 passed, 0 failed, 0 skipped on 2× B200 (log); the same command with
TORCH_CUDA_ARCH_LIST=9.0on 2× H100: 101 passed (log). Two GPUs are needed for the device-isolation test. The tests cover:Scope / Known limitations