Repository navigation
[WS1][Qwen-Image][CUDA] Final AdaLN output (final_adaln_out) - #538
fusheng-ji wants to merge 7 commits into
Conversation


Add the Qwen-Image Phase A `adaln_mod_projection` operator (RFC RL-Align#386):
per-stream SiLU + Linear 3072->18432 with a fixed-order FP32 forward,
compensated input gradients and ascending FP32 Neumaier parameter
gradients, plus an independent CPU FP32 reference.

Sources live under csrc/cuda/model_specific/qwenimage,
rl_engine/backends/cuda/model_specific/qwenimage and
rl_engine/reference/model_specific/qwenimage. Register the CUDA and CPU
slots (other platforms fail closed), the native bindings, the WS1
operator spec/inputs and the build source, and add tests, evidence
runners under benchmarks/models/qwenimage, and the operator page.

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
Add the Qwen-Image Phase A `final_adaln_out` operator (RFC RL-Align#386):
image-stream final modulation, LayerNorm(eps 1e-6) with SiLU + Linear
3072->6144 `(scale, shift)`, reusing the fixed-order projection from
`adaln_mod_projection` and adding a fixed-tree FP32 token reduction for
the modulation parameter gradients.

Register the CUDA and CPU slots (other platforms fail closed), the
token-sum binding, the WS1 operator spec/inputs and the build source,
and extend the tests, evidence runners and documentation to the final
stream.

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>


|
Important Review skippedAuto reviews are disabled on base/target branches other than the default branch. Please check the settings in the CodeRabbit UI or the
 |
 Flink-ddd
added
platform: cuda
The raw results (JSON, figures, audit files) now live on the fork's pr_assets branch;
the documents link to them at a fixed commit.

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
The raw results (JSON, figures, audit files) now live on the fork's pr_assets branch;
the documents link to them at a fixed commit.

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
2a8c166 to
8803403
Compare
…, PR RL-Align#538 FlashInfer DiT LayerNorm attempt

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
8803403 to
2d9680d
Compare
…Align#491 RL-Align#537 RL-Align#538 RL-Align#536 RL-Align#547.

Redacted logs, JSON, and summaries under pr<N>/hopper/.

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>

| v[i] = row < seq ? x[(batch * seq + row) * hidden + h] : 0.0f; | ||
| } | ||
| #pragma unroll | ||
| for (int stride = 1; stride < 32; stride *= 2) { |

There was a problem hiding this comment.
This tree gives 6020 instead of 6030 for the cancellation case already covered by the reference test. That exceeds the FP32 gradient tolerance and carries into the bias gradient. The CUDA path needs this regression test too.
There was a problem hiding this comment.
Thanks, reproduced: the CUDA tree returned 6020 on that input where the reference gives 6030. Fixed in 366bb9a (merged as e23c4a9): each 32-token tile now sums in ascending order with Neumaier compensation, and tile sums and corrections are folded level by level with one final IEEE add. The case now gives 6030, random inputs up to S=40000 are at the reference error level, and a sample reduced alone is byte-identical. Regression test: test_token_sum_retains_small_contributions_under_cancellation. The docs and readback now describe the new reduction.
| raise RuntimeError("Qwen-Image CUDA requires SM80 or newer") | ||
|
|
||
|
|
||
| def projection_forward(temb, weight, bias): |
There was a problem hiding this comment.
.contiguous() doesn't realign an already-contiguous view. A weight sliced with a one-element storage offset passes validation here but fails the kernel's 16-byte alignment check. These views need an explicit copy.
There was a problem hiding this comment.
Thanks, reproduced with a one-element storage offset in fp32 and bf16: validation passes and the kernel then rejects the weight. Fixed in 274b6c5: a new aligned() helper clones a tensor whose pointer is not 16-byte aligned, and the projection forward and backward use it for the weight, bias, activation and gradient. test_misaligned_storage_views_match_aligned_copies compares forward and gradient bytes against aligned copies; it fails without the fix.
…plicitly

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
…ve cancellation

Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>
Signed-off-by: Wenbo Ji <36562829+fusheng-ji@users.noreply.github.com>

# Conflicts:
#	tests/models/qwenimage/test_adaln.py

|
🔍 OpenCodeReview found 8 issue(s) in this PR.
📄
|


|
@fusheng-ji The automated OCR review has completed. Please review and address all automated review bot findings, then push your updates. Maintainers will begin manual review after the bot findings have been addressed. |


What
RFC #386 WS1 row
final_adaln_out: the image-stream final modulationnorm_out:Forward and backward are implemented. The later 3072 → 64
proj_outbelongs tolatent_proj_gemmand is not included.adaln_mod_projection's fixed-order CUDA projection and backward ([WS1][Qwen-Image][CUDA] AdaLN modulation projection (adaln_mod_projection) #537) unchanged.aten.native_layer_normandnative_layer_norm_backward), run on FP32 input with a declared execution-dtype store. Both are per-row, so batching does not change them; the BI checks above confirm this.d_scaleandd_shiftare token sums, reduced by a new FP32 kernel (csrc/cuda/model_specific/qwenimage/token_sum.cu) that applies fixed 32-way balanced trees recursively until one value remains. The tree depends only on the sequence length, not on B or batch position.qwenimage_final_adaln_out(CUDA only, no fallback; CPU maps to the reference; ROCm/NPU/MUSA fail closed), plus the WS1 operator spec/inputs, binding, build source anddocs/operators/qwenimage-final-adaln-out.md.benchmarks/models/qwenimage/streams.py), plus two reuse-survey modes for the LayerNorm part: Liger and flash-attention.Placement follows #537:
model_specific/qwenimage/.Prior art & reuse decision
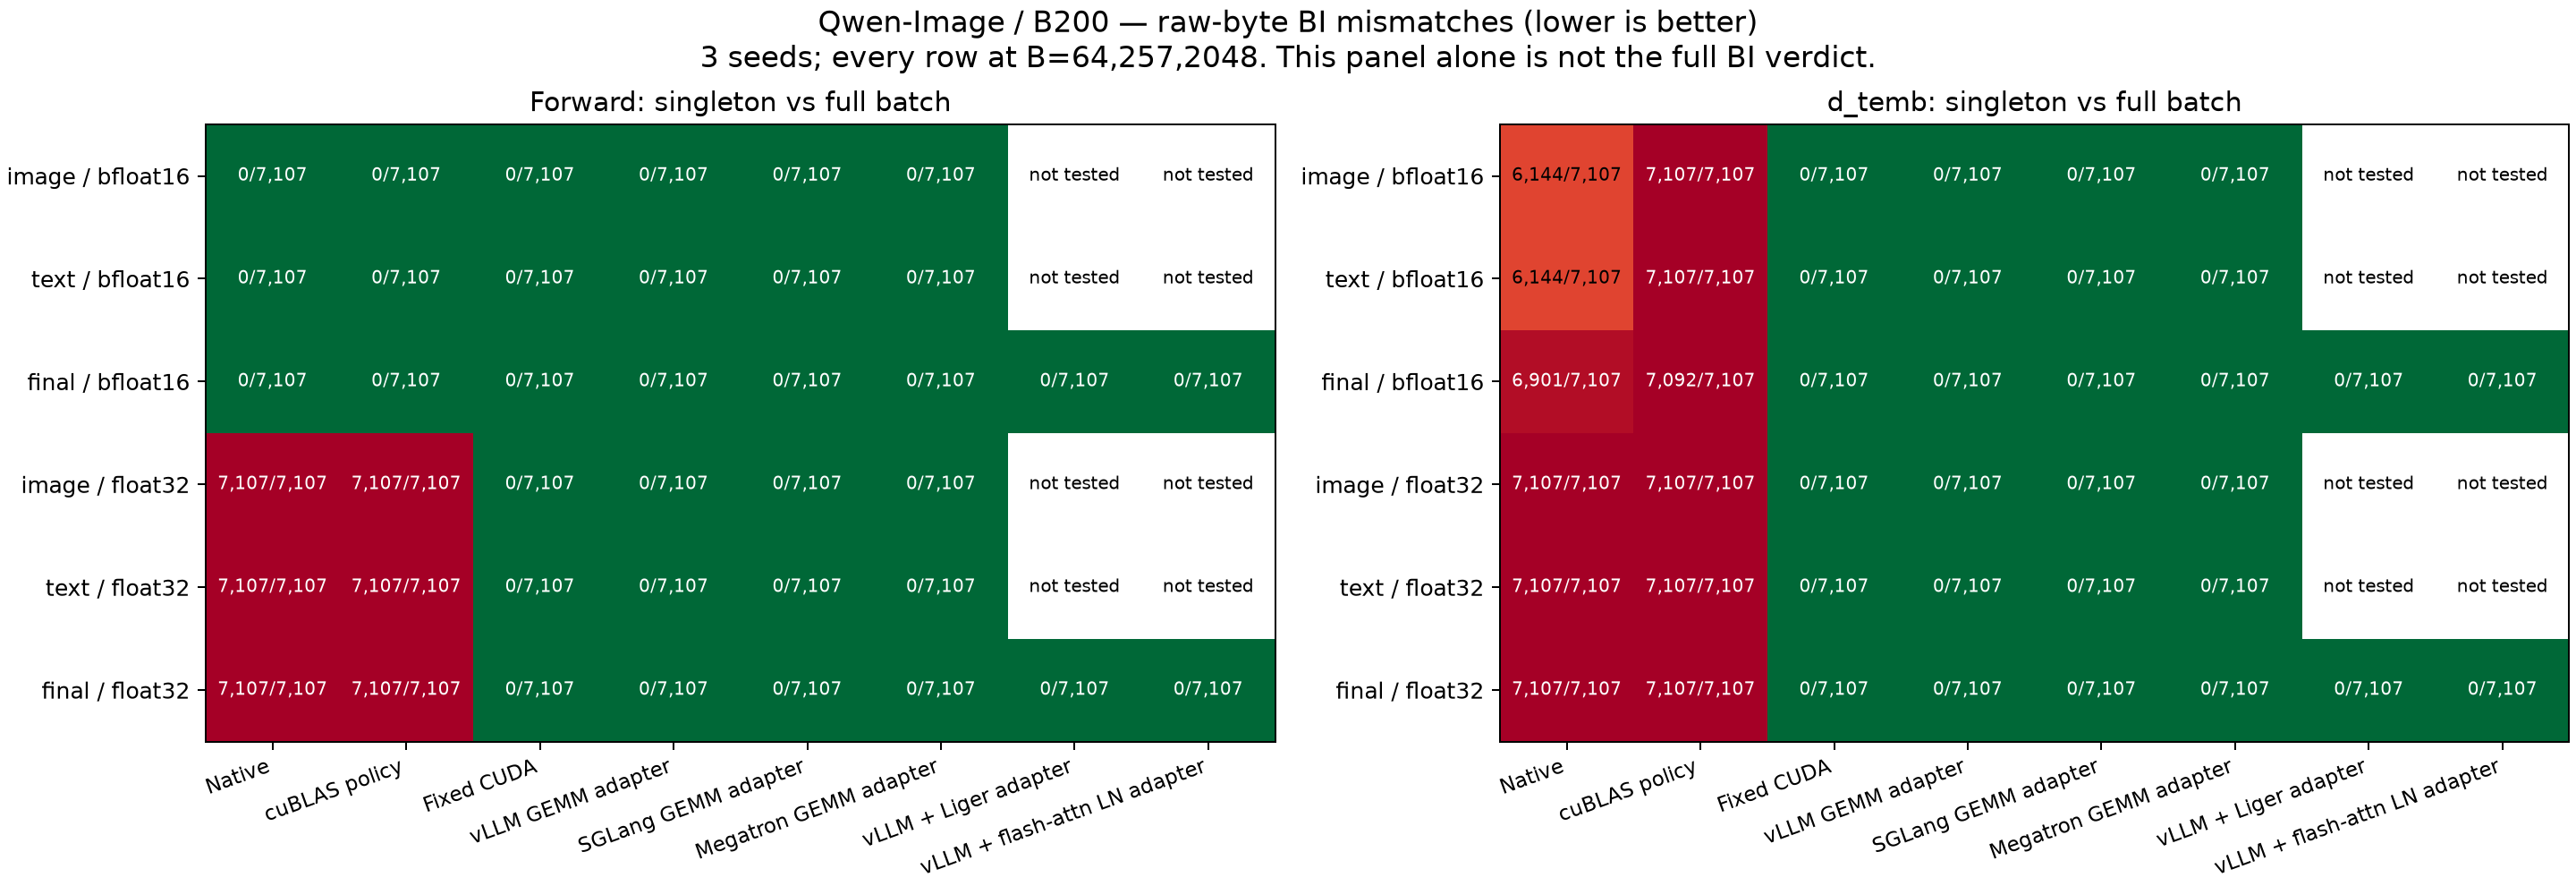
Each candidate composes an existing batch-invariant projection with an existing LayerNorm, and is measured on the full forward and backward path with the checkpoint's
norm_out.linearweights. BI is checked bytewise: a singleton vs every row of B = 64/257/2048, three seeds, dense and boundary batch sweeps, the 4096-sample workload in 5 chunkings, and B = 2 vs B = 1 at S = 31/32/33/4096/6889/6032.F.layer_norm+F.linear(cuBLAS), torch 2.13.0+cu130--mode native --phase bi: 581/816 records failbatch_invariant.py@7797b60GEMM +F.layer_norm--mode vllm_local: 4/816 fail (long sequences)d_weight40,442 elements over tolerance at S=6889CUBLAS_WORKSPACE_CONFIG=:16:8,CUBLASLT_WORKSPACE_SIZE=1batch_invariant_ops.py, sglang 0.5.21batch_invariant_kernels.py@52fbcbcliger_kernel/ops/layer_norm.py, liger-kernel 0.8.4, with the vLLM GEMMd_weight40,459 elements over tolerance at S=6889flash_attn/ops/triton/layer_norm.py@94e22c9(Triton, with backward), with the vLLM GEMMd_weight40,442 elements over tolerance at S=6889flashinfer/norm/__init__.py@34bb66efused_dit_residual_layernorm_scale_shift(+ gated variants)temb.chunk(6, dim=2)views), raisedillegal memory accessin every configuration tried (S = 4 to 4096, B = 1 to 4, with and without residual, fresh JIT cache), so no BI result exists; probe and error0b55a2f: examples only (e.g.37_gemm_layernorm_gemm_fusion)1d367a4/05bd9cb/b9ecdf5:git grep -iE 'img_mod|txt_mod|AdaLayerNormContinuous|adaln'→ no filesAdaLayerNormContinuousinnormalization.py@d961a38All five batch-invariant compositions also exceed the BF16 tolerance on
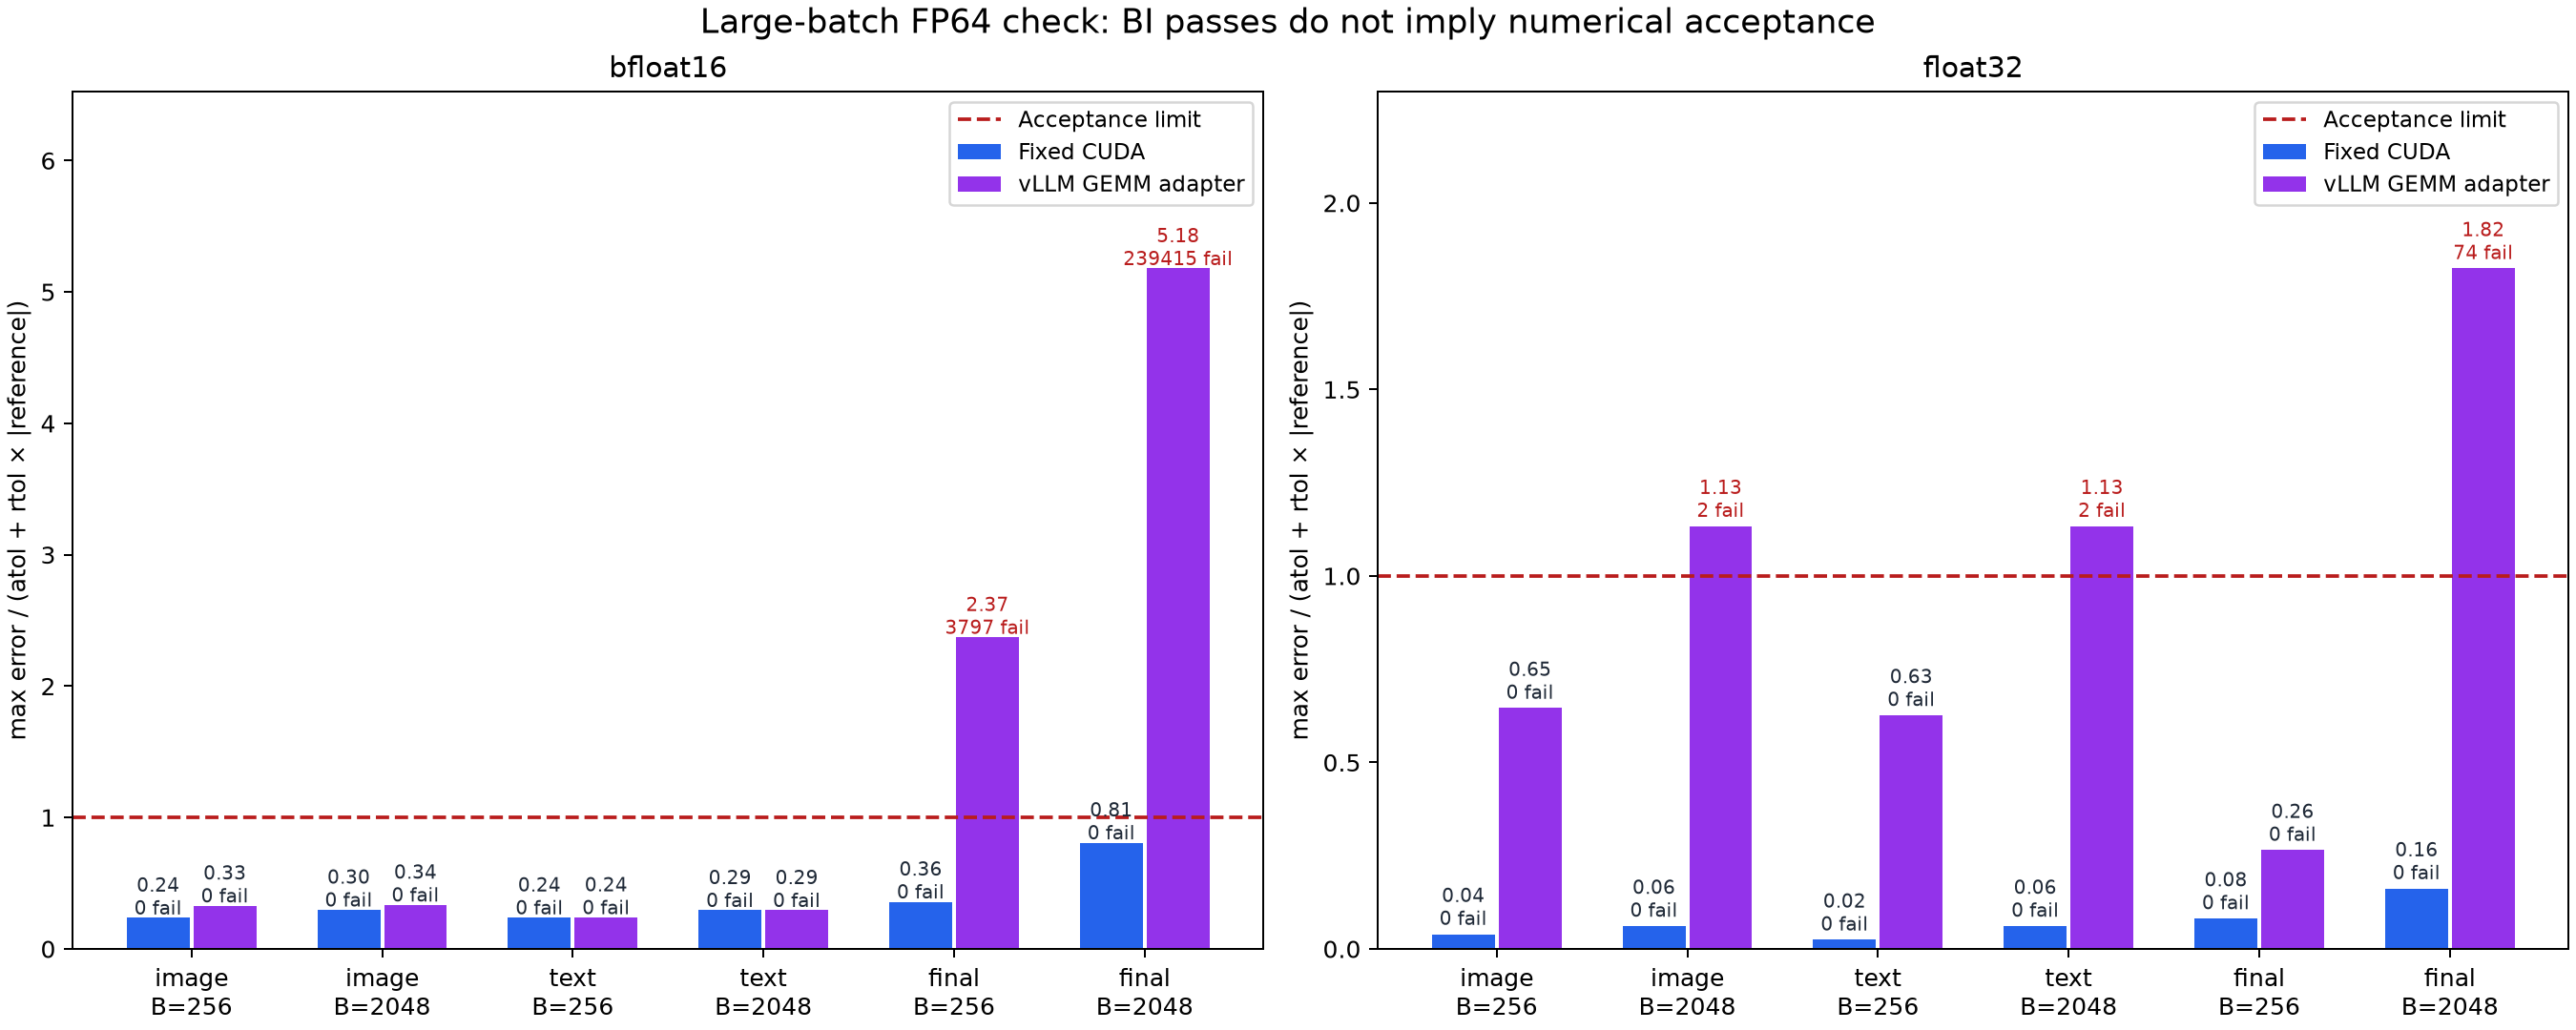
d_weight/d_bias:At FP32 B = 2048 they fail by 70–75 elements. In these compositions, the modulation backward and its token sums run through native autograd; this operator accumulates those sums in a fixed FP32 tree and passes every case.
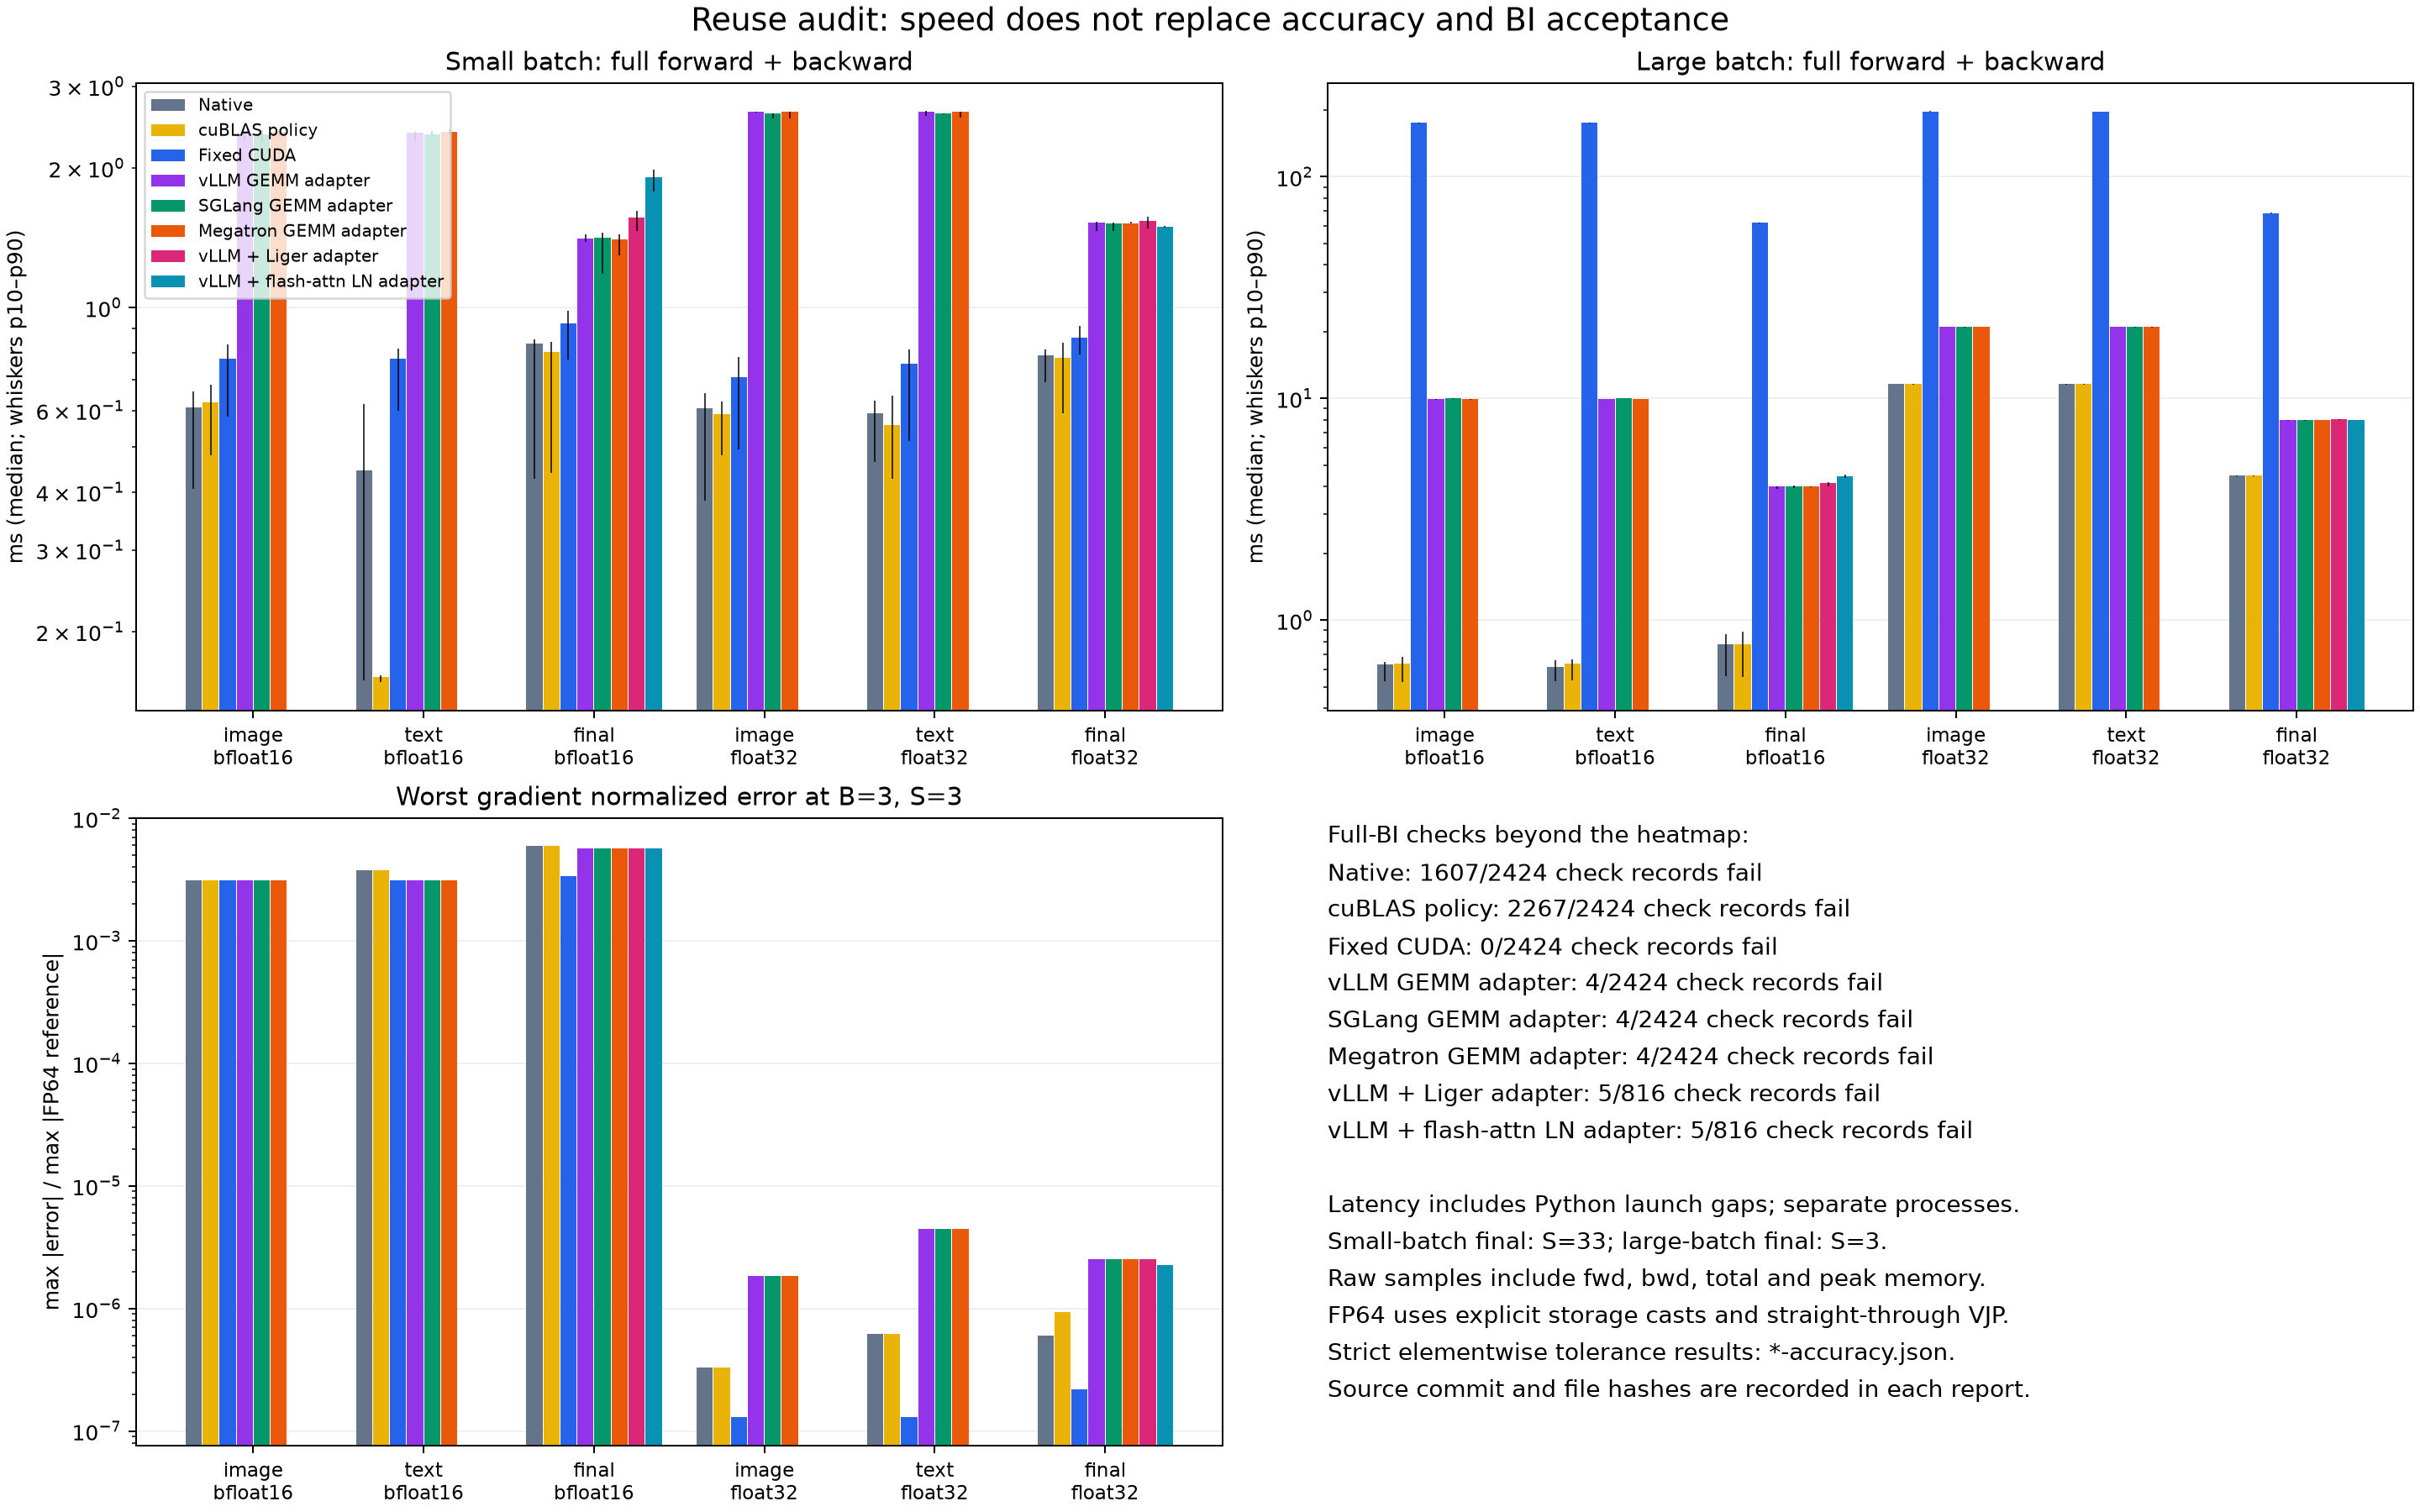
Final stream, forward + backward median ms:
F.layer_normDecision: write our own. No existing implementation is both batch-invariant and within the declared tolerances:
The operator is slower than these candidates at large conditioning batches; the projection reuse question in #537 applies to its projection part as well.
Results
Measured at
442e003166c14a12ff6c55032b2f0e1e391ef689. The evidence commit adds onlydocs/usage/evidence/qwenimage-final-adaln-out-b200/.fixed/acceptance.json is qualified with zero failures (all three streams are revalidated at this commit):
Accuracy (strict FP64 acceptance; this operator vs the BI compositions):
Batch invariance:
Performance (all candidates; and this operator vs native PyTorch at B=1):
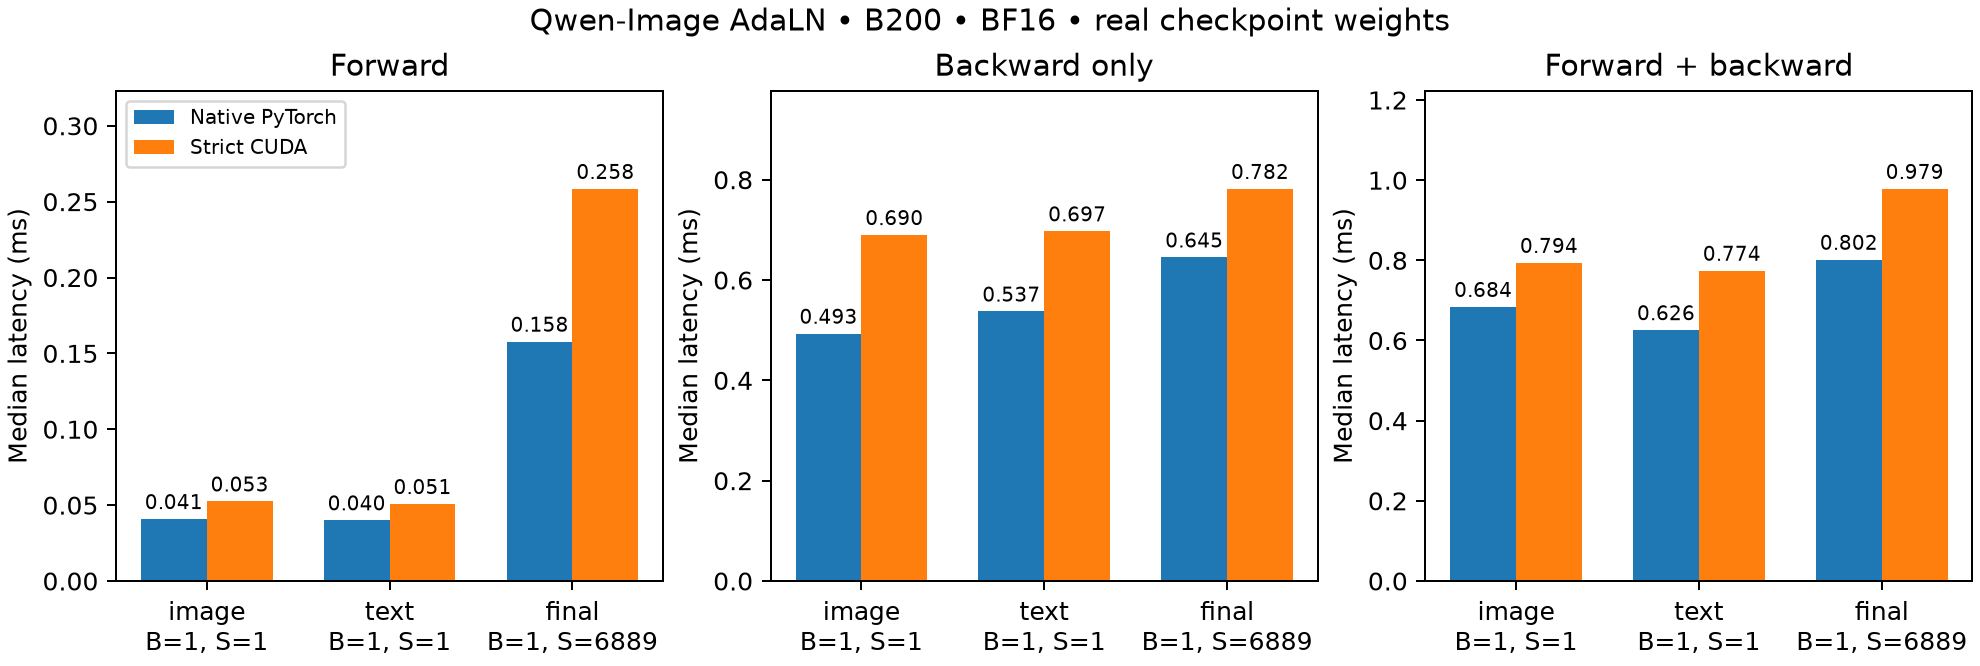
At B=1, S=6889 (BF16) the operator takes 0.979 ms forward + backward vs 0.802 ms for native PyTorch. Peak memory is 605.5 MiB vs 350.4 MiB, because the operator keeps FP32 normalization state. Environment: B200 (SM100), PyTorch 2.13.0+cu130, CUDA 13.0, driver 580.126.20, TF32 off, no fast-math. Full evidence, pins and reproduction: README.
Results (H100 sm90, head
e23c4a97)Measured at
e23c4a97c0ce3038a08943d7fa150077e4a5c707on H100-94GB (SM90), stacked on #537. Raw logs and JSON:pending/h100-rerun-20261028/pr538/(commit1dd3e8fc). The measurement at the earlier head2d9680d7stays underpr538/hopper/onpr_assets. Since2d9680d7the head contains the #537 changes (strict-math probe, aligned copies) and a rewrittentoken_sum.cu(Neumaier-compensated 32-token tiles, folded level by level).fixed/acceptance.json is qualified with zero failures (2738 checks, all three streams; same gates and counts as at
2d9680d7):Long-sequence cases S = 4096 / 6889 / 6032 are covered in the fixed-mode audit JSON under
acceptance/fixed/(seeaccuracy_large-*.json). The cancellation case (S = 6032, one token of 2^26 and one of -2^26 around ones) gives 6030 in all three columns on H100 (token_sum_probe.log); the previous plain 32-token tree gave 6020.qwenimage_strict_math_compiled()returnsTrue(strict_math_probe.log). Within-H100 invariance only; no cross-architecture byte equality vs B200. Environment matches #537 H100 run (TORCH_CUDA_ARCH_LIST=9.0). Run description:README.md,tests.json,env.txt.Status
No known failures at
dbc3e20f6e45ffcea7f73c05fbaa76ec02ff3670. Evidence was produced from a clean checkout of the code commit442e003166c14a12ff6c55032b2f0e1e391ef689, which is this PR's parent of the evidence commit. Stacked on #537; review that first.Tests
135 passed, 0 failed, 0 skipped on 2× B200 at the earlier head
2d9680d7(log); on 2× H100 at the current heade23c4a97: 140 passed, 0 failed, 0 skipped (log). The 5 added tests are the strict-math build test (2), the misaligned-view test (2 dtypes) and the token-sum cancellation test. The B200 count has not been re-run at the current head. That is 105 from #537 and 35 added here on H100 (101 and 34 at the B200 count). The added tests cover:(scale, shift)order and LayerNorm.Scope / Known limitations
norm_outonly;proj_outbelongs tolatent_proj_gemm. First-order autograd only. Long token counts and large batches are covered separately, not every B×S combination.