


Skip to content
View dolev31's full-sized avatar

Highlights

  • Pro

Block or report dolev31

Block user

Prevent this user from interacting with your repositories and sending you notifications. Learn more about blocking users.

You must be logged in to block users.

Content in all repositories owned by your account will be closed.
Maximum 250 characters. Please don’t include any personal information such as legal names or email addresses. Markdown is supported. This note will only be visible to you.
Report abuse

Contact GitHub support about this user’s behavior. Learn more about reporting abuse.

Report abuse
dolev31/README.md

Ido Levy

Research on LLM agents at IBM and the Weizmann Institute of Science:
what agents pursue without being asked, and how safely they act.

Google Scholar LinkedIn Hugging Face New paper


🧱 Retrieval Augmented Generation Compositionality · Lasagna · 2026

Ido Levy, Segev Shlomov, Leshem Choshen
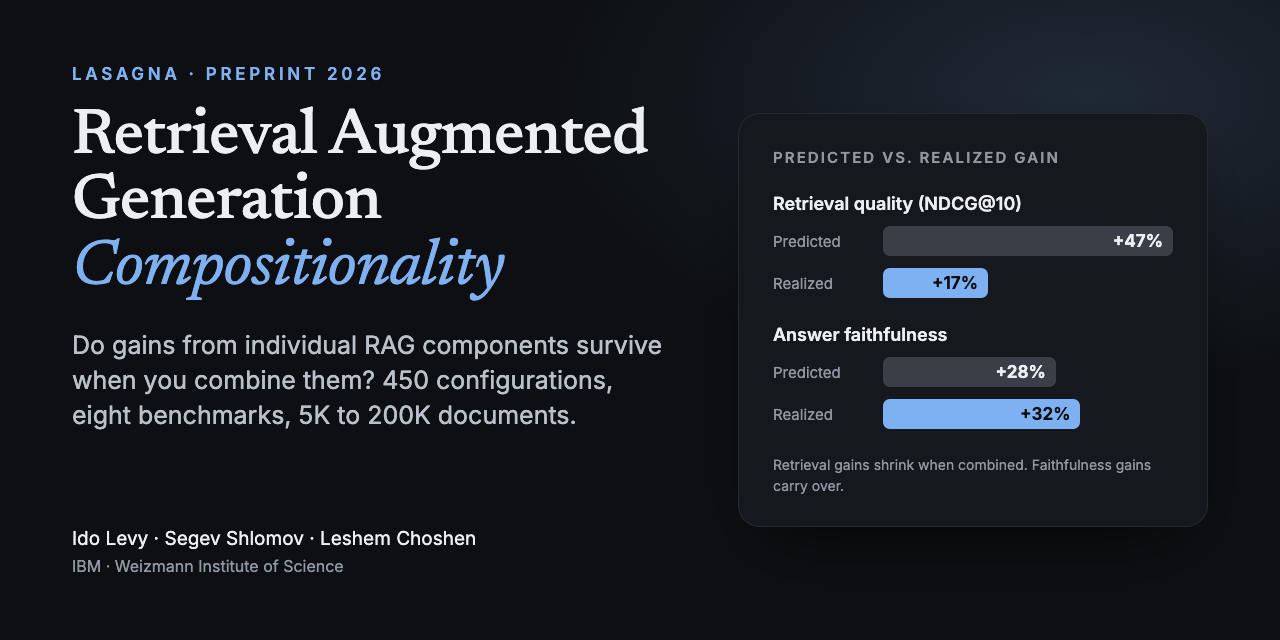
Retrieval Augmented Generation Compositionality, by Ido Levy, Segev Shlomov and Leshem Choshen. Predicted versus realized gain: retrieval quality (NDCG@10) +47% predicted, +17% realized; answer faithfulness +28% predicted, +32% realized.

RAG techniques are usually tested one at a time. Do their gains survive when they are combined? Across 450 configurations, eight benchmarks and corpora from 5K to 200K documents, the three strongest single retrieval techniques predict a +47% gain in NDCG@10 when combined and deliver +17%, and the pipeline that leads on small corpora trails by 13.7% NDCG@10 at 200K documents. Lasagna, the open-source framework behind the study, swaps one stage of a RAG pipeline while holding the rest fixed and tests whether the difference is real.

Stars

Paper · Project page · Code · PyPI · Pre-registration

⚡ TabAgent: Distilling LLM Agent Components into Cheap Classifiers · 2026

Ido Levy, Segev Shlomov, Avi Yaeli, Nir Mashkif, Asaf Adi, Yinon Goldstein, Eilam Shapira, Leshem Choshen
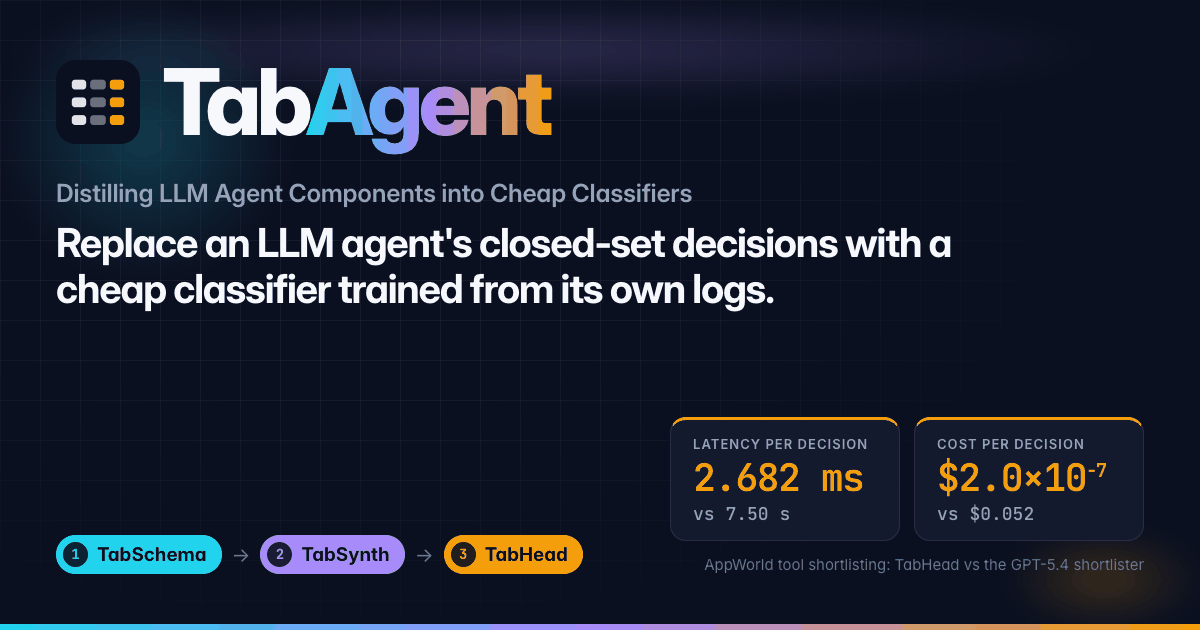
TabAgent: replace an LLM agent's closed-set decisions with a cheap classifier trained from its own logs

Agents call a frontier LLM again and again for closed-set decisions: which tools to shortlist, which skill or application to use, where to route. TabAgent replaces that call with a compact classifier trained on the agent's own successful runs, leaving the rest of the agent intact. On tool shortlisting it recovers essentially all of the tools the GPT-5.4 shortlister used on its successful runs, at about 10³× lower latency and 10⁵× lower cost per call.

Stars PyPI

Paper · Project page · Code · Models 🤗

🔎 Asking for What Was Never Requested: Horizontal and Vertical Proactivity in Agents · 2026

Ido Levy, Asaf Yehudai, Segev Shlomov, Asaf Adi, Leshem Choshen
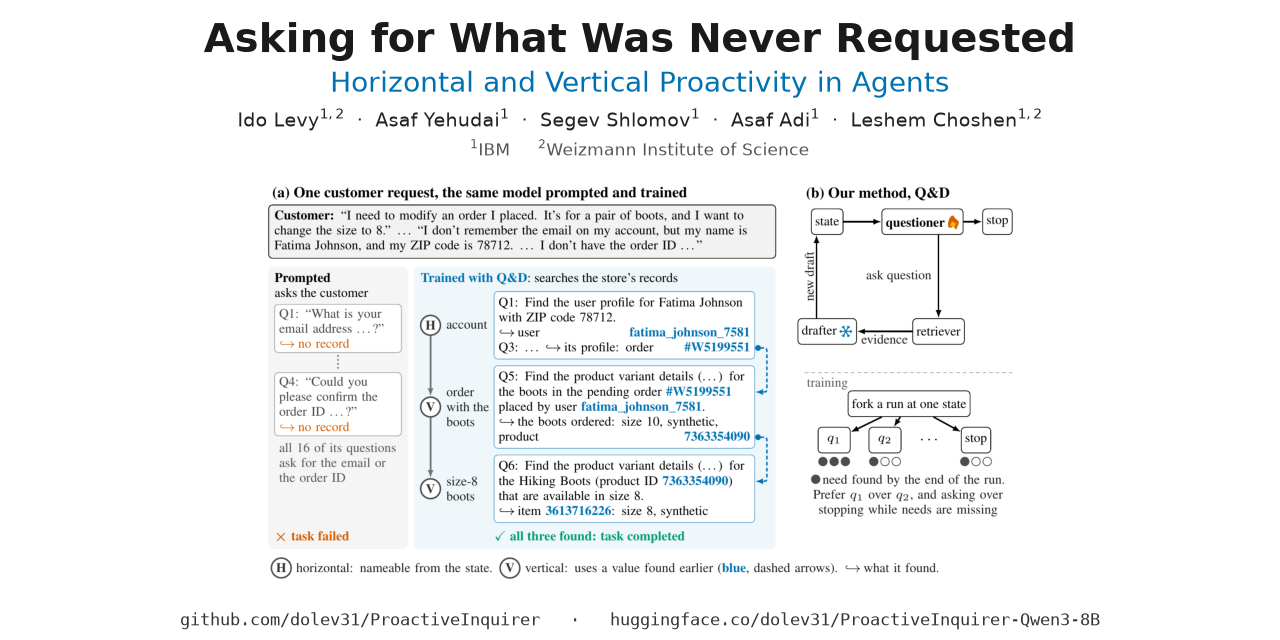
Asking for What Was Never Requested: one customer request handled by the same model, prompted and trained with Q&D

What should an LLM agent pursue that the user never asked for? Need graphs measure it without a model judge, and Q&D trains it from the consequences of its own questions. The trained 8B questioner recovers 90% of the required evidence where the same model, prompted, recovers 78%, and it more than doubles retail task success in a τ²-bench customer-service agent it was never trained on.

Stars

Paper · Project page · Code · Model 🤗

🛡️ ST-WebAgentBench: A Benchmark for Evaluating Safety and Trustworthiness in Web Agents · 2024

Ido Levy, Ben Wiesel, Sami Marreed, Alon Oved, Avi Yaeli, Segev Shlomov

A benchmark for evaluating the safety and trustworthiness of web agents in enterprise scenarios.

Stars

Paper · Website · Code · Leaderboard · Dataset

🧩 CUGA: an open-source generalist agent for the enterprise · contributor

Stars

An agent harness for complex tasks on the web and APIs, with OpenAPI and MCP integrations, a composable architecture, reasoning modes and policy-aware features.

Website · Code

Pinned Loading

  1. ProactiveInquirer ProactiveInquirer Public

    Asking for What Was Never Requested: horizontal and vertical proactivity in LLM agents. Need-graph metrics (no LLM judge) and Q&D, which trains a questioner from the consequences of its questions.

    Python 15

  2. cuga-project/cuga-agent cuga-project/cuga-agent Public

    CUGA is an open-source generalist agent harness for the enterprise, supporting complex task execution on web and APIs, OpenAPI/MCP integrations, composable architecture, reasoning modes, and policy…

    Python 1.1k 197

  3. segev-shlomov/ST-WebAgentBench segev-shlomov/ST-WebAgentBench Public

    A Benchmark for Evaluating Safety and Trustworthiness in Web Agents for Enterprise Scenarios

    Python 30 9

  4. lasagna lasagna Public

    Swap one RAG pipeline stage, hold the rest fixed, and measure whether the gain survives composition. The framework behind "Retrieval Augmented Generation Compositionality": 450 configurations, eigh…

    Python 23 5

  5. TabAgent TabAgent Public

    Replace an LLM agent's closed-set decisions with a cheap classifier trained from its own logs. Code for the paper TabAgent: Distilling LLM Agent Components into Cheap Classifiers.

    Python 4