diff --git a/content/docs/configuration/authentication/OAuth2-OIDC/auth0.mdx b/content/docs/configuration/authentication/OAuth2-OIDC/auth0.mdx
index d47b8a48d..1dca4a3cb 100644
--- a/content/docs/configuration/authentication/OAuth2-OIDC/auth0.mdx
+++ b/content/docs/configuration/authentication/OAuth2-OIDC/auth0.mdx
@@ -123,12 +123,18 @@ OPENID_SCOPE=openid profile email offline_access
# IMPORTANT: Your Auth0 API identifier (from Step 3)
OPENID_AUDIENCE=https://api.librechat.ai
+# Sent as the audience on refresh-token requests so refreshed tokens keep it
+OPENID_REFRESH_AUDIENCE=https://api.librechat.ai
+
# Security Settings (recommended)
OPENID_USE_PKCE=true
# Session Configuration (generate a secure random string)
OPENID_SESSION_SECRET=your-secure-session-secret-32-chars-or-more
+# Required for the OpenID login button to appear
+ALLOW_SOCIAL_LOGIN=true
+
# Maximum logout URL length before using logout_hint instead of id_token_hint (default: 2000)
# OPENID_MAX_LOGOUT_URL_LENGTH=2000
@@ -179,6 +185,12 @@ When `OPENID_AUDIENCE` is configured:
'The identifier of your Auth0 API. Required when using OPENID_REUSE_TOKENS=true with Auth0 to prevent opaque token issues. Comma-separated values are accepted for JWT validation; authorization requests use the first non-empty value.',
'OPENID_AUDIENCE=https://api.librechat.ai',
],
+ [
+ 'OPENID_REFRESH_AUDIENCE',
+ 'string',
+ 'Optional audience sent on refresh-token requests. Usually the same value as OPENID_AUDIENCE. Set it when Auth0 returns tokens for a different audience (or opaque tokens) after a refresh.',
+ 'OPENID_REFRESH_AUDIENCE=https://api.librechat.ai',
+ ],
]}
/>
@@ -193,6 +205,7 @@ When `OPENID_AUDIENCE` is configured:
1. Ensure `OPENID_AUDIENCE` is set to your Auth0 API identifier
2. Verify the API was created in Auth0 and offline access is enabled
3. Check that the audience value matches exactly
+4. Set `OPENID_REFRESH_AUDIENCE` to the same API identifier so refreshed access tokens keep the audience
### Invalid Token Errors
diff --git a/content/docs/configuration/authentication/OAuth2-OIDC/aws.mdx b/content/docs/configuration/authentication/OAuth2-OIDC/aws.mdx
index cfe3c1ead..a1bbe9e94 100644
--- a/content/docs/configuration/authentication/OAuth2-OIDC/aws.mdx
+++ b/content/docs/configuration/authentication/OAuth2-OIDC/aws.mdx
@@ -108,6 +108,9 @@ OPENID_SESSION_SECRET=Any random string
OPENID_SCOPE=openid profile email
OPENID_CALLBACK_URL=/oauth/openid/callback
+# Required for the OpenID login button to appear
+ALLOW_SOCIAL_LOGIN=true
+
# Optional: redirects the user to the end session endpoint after logging out
OPENID_USE_END_SESSION_ENDPOINT=true
# Maximum logout URL length before using logout_hint instead of id_token_hint (default: 2000)
diff --git a/content/docs/configuration/authentication/OAuth2-OIDC/index.mdx b/content/docs/configuration/authentication/OAuth2-OIDC/index.mdx
index 230ab714b..c1d246bc4 100644
--- a/content/docs/configuration/authentication/OAuth2-OIDC/index.mdx
+++ b/content/docs/configuration/authentication/OAuth2-OIDC/index.mdx
@@ -50,6 +50,18 @@ If you encounter issues with OpenID Connect authentication:
5. **Validate Tokens**: Ensure your provider is issuing valid tokens with the expected claims
6. **Ensure _nonce_ is generated**: Some identity providers generate `nonce` url parameter if it's missing in the request. Set `OPENID_GENERATE_NONCE=true` to force the openid-client to generate it.
+### Discovery Retries
+
+If your identity provider is unreachable when LibreChat starts, OpenID discovery can be retried. `OPENID_DISCOVERY_RETRY_ATTEMPTS` sets the number of attempts made before startup continues (0 to 100, default 1; `0` retries only in the background), and `OPENID_DISCOVERY_RETRY_DELAY_MS` sets the delay between attempts (default 5000). Values set under `registration.openidDiscovery` in `librechat.yaml` take precedence. See [registration](/docs/configuration/librechat_yaml/object_structure/registration) for those keys and for `oauthStateTtlMs`, which controls how long a started social login may take to reach its callback (default 10 minutes).
+
+### Profile Avatar Origins
+
+When fetching the user's profile avatar, LibreChat sends the access token only to the provider's issuer and userinfo origins. If the avatar is served from another origin that requires the token, add it to `OPENID_AVATAR_AUTHORIZED_ORIGINS` as a comma- or space-separated list of URLs.
+
+```bash filename=".env"
+OPENID_AVATAR_AUTHORIZED_ORIGINS=https://graph.example.com,https://photos.example.com
+```
+
### Admin Panel Redirects
If the Admin Panel is hosted on a separate URL from LibreChat, set [`ADMIN_PANEL_URL`](/docs/features/admin_panel#librechat-redirect-url) in the LibreChat API environment. This tells LibreChat where to send admins after the admin OAuth or SSO callback completes.
diff --git a/content/docs/configuration/authentication/OAuth2-OIDC/keycloak.mdx b/content/docs/configuration/authentication/OAuth2-OIDC/keycloak.mdx
index 7e1cf6ea1..4d070a638 100644
--- a/content/docs/configuration/authentication/OAuth2-OIDC/keycloak.mdx
+++ b/content/docs/configuration/authentication/OAuth2-OIDC/keycloak.mdx
@@ -65,6 +65,9 @@ If you want to restrict access to users with specific roles, you can define role
OPENID_REQUIRED_ROLE_TOKEN_KIND=(access|id) # that means, `access` or `id`
OPENID_REQUIRED_ROLE_PARAMETER_PATH="realm_access.roles"
+ # Required for the OpenID login button to appear
+ ALLOW_SOCIAL_LOGIN=true
+
# Optional: redirects the user to the end session endpoint after logging out
OPENID_USE_END_SESSION_ENDPOINT=true
diff --git a/content/docs/configuration/authentication/OAuth2-OIDC/token-reuse.mdx b/content/docs/configuration/authentication/OAuth2-OIDC/token-reuse.mdx
index c39f34505..56898f53d 100644
--- a/content/docs/configuration/authentication/OAuth2-OIDC/token-reuse.mdx
+++ b/content/docs/configuration/authentication/OAuth2-OIDC/token-reuse.mdx
@@ -111,10 +111,11 @@ OPENID_REUSE_MAX_SESSION_AGE_MS=900000 # 15 minutes in milliseconds
# Required for Auth0 (use your API identifier)
# OPENID_AUDIENCE=https://api.librechat.com
+# OPENID_REFRESH_AUDIENCE=https://api.librechat.com
# Caching Configuration
OPENID_JWKS_URL_CACHE_ENABLED=true
-OPENID_JWKS_URL_CACHE_TIME=600000 # 10 minutes in milliseconds
+OPENID_JWKS_URL_CACHE_TIME=600000 # 10 minutes in milliseconds (default: 60000, 1 minute)
# Azure-specific Configuration
OPENID_ON_BEHALF_FLOW_FOR_USERINFO_REQUIRED=true
@@ -132,10 +133,11 @@ OPENID_USE_END_SESSION_ENDPOINT=true
## Additional Configuration Options
- `OPENID_AUDIENCE`: Audience value for JWT validation and authorization requests. **Required for Auth0** to receive JWT access tokens instead of opaque tokens. Comma-separated values are accepted for JWT validation; authorization requests use the first non-empty value.
+- `OPENID_REFRESH_AUDIENCE`: Optional audience sent on refresh-token requests, usually the same value as `OPENID_AUDIENCE`. Needed by providers such as Auth0 when a custom API must keep its audience across refreshes.
- `OPENID_REUSE_MAX_SESSION_AGE_MS`: Maximum age a reused OpenID session token is served before LibreChat forces an IdP refresh (default: 900000 ms / 15 minutes). Accepts arithmetic expressions like `60 * 60 * 24 * 1000`. Increase it toward your IdP access-token lifetime if your provider revokes the previous access token whenever it refreshes.
- `OPENID_REFRESH_BRIDGE_GRACE_MS`: Short recovery window for a rotated refresh token while LibreChat publishes the refreshed session (default: 60000 ms / 1 minute). It accepts arithmetic expressions. Increase it only when slow session persistence or cross-replica publication needs more time.
-- `OPENID_JWKS_URL_CACHE_ENABLED`: Enables caching of signing key verification results to prevent excessive HTTP requests to the JWKS endpoint
-- `OPENID_JWKS_URL_CACHE_TIME`: Cache duration in milliseconds (default: 600000 ms / 10 minutes)
+- `OPENID_JWKS_URL_CACHE_ENABLED`: Caches signing keys to prevent excessive HTTP requests to the JWKS endpoint. Caching is enabled when this is unset; any value other than `true` disables it.
+- `OPENID_JWKS_URL_CACHE_TIME`: Cache duration in milliseconds (default: 60000 ms / 1 minute)
- `OPENID_ON_BEHALF_FLOW_FOR_USERINFO_REQUIRED`: Enables on-behalf-of flow for user info (Azure-specific)
- `OPENID_ON_BEHALF_FLOW_USERINFO_SCOPE`: Scope for user info in on-behalf-of flow (Azure-specific)
- `GRAPH_API_SCOPES`: Space-separated Microsoft Graph scopes requested when resolving `{{LIBRECHAT_GRAPH_ACCESS_TOKEN}}` in a YAML-defined MCP server. Defaults to `https://graph.microsoft.com/.default`; this is separate from the `OPENID_GRAPH_SCOPES` used for people and group search.
diff --git a/content/docs/configuration/authentication/ldap.mdx b/content/docs/configuration/authentication/ldap.mdx
index 676ce8207..7178317a4 100644
--- a/content/docs/configuration/authentication/ldap.mdx
+++ b/content/docs/configuration/authentication/ldap.mdx
@@ -72,7 +72,7 @@ and configure LibreChat to request login via username:
options={[
[
'LDAP_LOGIN_USES_USERNAME',
- 'string',
+ 'boolean',
'Use username instead of email.',
'LDAP_LOGIN_USES_USERNAME=true',
],
@@ -81,10 +81,15 @@ and configure LibreChat to request login via username:
**Active Directory over SSL**
-To connect via SSL (ldaps://), such as a company using Windows AD, specify the path to the internal CA certificate.
-`LDAP_TLS_REJECT_UNAUTHORIZED` is optional;if not specified LibreChat will reject TLS/SSL connections if the LDAP server's certificate cannot be verified.
-set `LDAP_TLS_REJECT_UNAUTHORIZED` to false (not recommended for production environments)
-to allow Librechat to accept TLS/SSL connections even if the LDAP server's certificate cannot be verified,
+To connect via SSL (ldaps://), such as a company using Windows AD, specify the path to the internal CA certificate with `LDAP_CA_CERT_PATH`.
+
+`LDAP_TLS_REJECT_UNAUTHORIZED` is only applied when `LDAP_CA_CERT_PATH` is set. In that case, certificate verification is **off** unless you explicitly set `LDAP_TLS_REJECT_UNAUTHORIZED=true`. When `LDAP_CA_CERT_PATH` is not set, LibreChat passes no TLS options and the default Node.js behavior applies (the server certificate is checked against the system trust store).
+
+
+ If you set `LDAP_CA_CERT_PATH` without `LDAP_TLS_REJECT_UNAUTHORIZED=true`, LibreChat trusts any
+ certificate presented by the LDAP server, which exposes bind credentials and user passwords to
+ man-in-the-middle attacks. Always set `LDAP_TLS_REJECT_UNAUTHORIZED=true` in production.
+
- - **Display From/To**: When the banner should appear and disappear. Leave empty for "now" and "forever"
+ - **Display From/To**: When the banner should appear and disappear. Press Enter at the prompt to use "now" and "forever"
- **Is public**: Show to visitors who aren't logged in (like on the login page)
- - **Is persistable**: If yes, users can't dismiss the banner — use for important notices
+ - **Is persistable**: If yes, users can't dismiss the banner (use it for important notices)
@@ -68,8 +74,16 @@ To change a banner, run `update-banner` again. To take one down before its `Disp
npm run delete-banner
```
+With Docker, run `docker compose exec api npm run delete-banner`.
+
You'll see the current banner and be asked to confirm before deleting.
+
+
+`delete-banner` only finds a banner that is currently active: its `Display From` time must have passed, and its `Display To` time must be in the future or not set. A banner scheduled for a later date, or one whose `Display To` has already passed, is reported as "No banner found to delete" and stays in the database. To replace such a banner, run `update-banner` again.
+
+
+
Removing a banner this way is also how you take one down early: there is no "disable" flag. A banner otherwise disappears on its own once `Display To` passes, and one saved with no `Display To` stays up until you delete it.
---
@@ -100,6 +114,12 @@ Removing a banner this way is also how you take one down early: there is no "dis
+
+
+An empty string (`""`) for a date is treated as missing, so the script still asks for `Display From` and `Display To` interactively. Press Enter at each prompt to accept the default, or pass ISO dates (`yyyy-mm-ddTHH:MM:SSZ`) as the first two arguments to run the command without prompts. The message argument is also required to skip the message prompt, and the `isPublic` and `persistable` arguments must be given as `true` or `false` to skip theirs.
+
+
+
---
## Date Format
@@ -110,4 +130,4 @@ Use this format for dates: `yyyy-mm-ddTHH:MM:SSZ`
- `2025-12-25T09:00:00Z` → December 25, 2025 at 9:00 AM (UTC)
- `2025-01-01T00:00:00Z` → January 1, 2025 at midnight (UTC)
-Leave the date empty to use the current time or no end date.
+When prompted, press Enter without typing a date to use the current time for `Display From`, or no end date for `Display To`.
diff --git a/content/docs/configuration/cdn/azure.mdx b/content/docs/configuration/cdn/azure.mdx
index 2849bddd1..f3e3dd33d 100644
--- a/content/docs/configuration/cdn/azure.mdx
+++ b/content/docs/configuration/cdn/azure.mdx
@@ -76,7 +76,7 @@ AZURE_CONTAINER_NAME=files
- **AZURE_STORAGE_CONNECTION_STRING:** Set this if you are using Option A.
- **AZURE_STORAGE_ACCOUNT_NAME:** Set this if you are using Option B (Managed Identity). Do not set both.
-- **AZURE_STORAGE_PUBLIC_ACCESS:** Set to `false` if you do not want your blobs to be publicly accessible by default. Set to `true` if you need public access (for example, for publicly viewable images).
+- **AZURE_STORAGE_PUBLIC_ACCESS:** Defaults to `true` when unset, which creates the container with public blob access. Set to `false` if you do not want your blobs to be publicly accessible, which is recommended unless you need public access (for example, for publicly viewable images).
- **AZURE_CONTAINER_NAME:** This is the container name your application will use (e.g., `files`). The application will automatically create this container if it doesn’t exist.
## 4. Configure LibreChat to Use Azure Blob Storage
@@ -90,7 +90,7 @@ fileStrategy: "azure_blob"
```
- Azure Blob Storage stores and serves files directly from origin — it is not a CDN. Images and avatars are best served through a CDN for optimal performance and global delivery. Currently, [Firebase](/docs/configuration/cdn/firebase) is the only CDN-backed storage option.
+ Azure Blob Storage stores and serves files directly from origin, so it is not a CDN. Images and avatars are best served through a CDN for optimal performance and global delivery. [CloudFront](/docs/configuration/cdn/cloudfront) (S3-backed) and [Firebase](/docs/configuration/cdn/firebase) are the CDN-backed storage options.
You can use `fileStrategies` to route only avatars and images to Firebase while keeping documents on Azure Blob Storage:
diff --git a/content/docs/configuration/cdn/s3.mdx b/content/docs/configuration/cdn/s3.mdx
index b951700d0..7bc8f90c5 100644
--- a/content/docs/configuration/cdn/s3.mdx
+++ b/content/docs/configuration/cdn/s3.mdx
@@ -104,7 +104,7 @@ AWS_ENDPOINT_URL=https://your_endpoint_url
- **AWS_BUCKET_NAME:** The name of the S3 bucket you created.
- **AWS_ENDPOINT_URL:** (Optional) The custom AWS endpoint URL. Required for S3-compatible services such as MinIO, Cloudflare R2, Hetzner Object Storage, Backblaze B2, and IDrive e2. Include the URL scheme, such as `https://a7g8.da.idrivee2-32.com`; values without `http://` or `https://` can cause an `Invalid URL` error when files are streamed.
- **AWS_FORCE_PATH_STYLE:** (Optional) Set to `true` for providers that require path-style URLs (`endpoint/bucket/key`) rather than virtual-hosted-style (`bucket.endpoint/key`). Required for Hetzner Object Storage, MinIO, and similar providers whose SSL certificates don't cover bucket subdomains. Not needed for AWS S3 or Cloudflare R2. Default: `false`.
-- **S3_URL_EXPIRY_SECONDS:** (Optional) Lifetime of each presigned URL, in seconds. See the note on presigned URLs below for the provider-side caps that apply.
+- **S3_URL_EXPIRY_SECONDS:** (Optional) Lifetime of each presigned URL, in seconds. Default: 120 (2 minutes). Values above 604800 (7 days) are capped at 7 days, and an invalid or non-positive value falls back to 120. See the note on presigned URLs below for the provider-side caps that apply.
- **S3_REFRESH_EXPIRY_MS:** (Optional) Regenerate a presigned URL once it reaches this age, in milliseconds, instead of using the default expiry-buffer logic. Unset by default. A value that is not a positive integer is ignored with a warning in the logs.
If you are using **IRSA** on Kubernetes, you do **not** need to set `AWS_ACCESS_KEY_ID` and `AWS_SECRET_ACCESS_KEY` in your environment. The AWS SDK will automatically obtain temporary credentials via the service account assigned to your pod. Ensure that `AWS_REGION` and `AWS_BUCKET_NAME` are still provided.
@@ -133,6 +133,8 @@ fileStrategies:
document: 's3'
```
+`fileStrategies` also accepts `default` (the fallback for any type without its own entry) and `skills` (skill files). See [fileStrategies](/docs/configuration/librechat_yaml/object_structure/config#filestrategies) for all keys.
+
## Summary
diff --git a/content/docs/configuration/index.mdx b/content/docs/configuration/index.mdx
index e4c9657d4..6d3a67fa9 100644
--- a/content/docs/configuration/index.mdx
+++ b/content/docs/configuration/index.mdx
@@ -4,7 +4,7 @@ icon: BookOpen
description: How LibreChat's configuration files work together and how to apply changes
---
-LibreChat uses four main configuration files. Each controls a different aspect of the application -- from environment variables to custom AI endpoints to Docker service overrides.
+LibreChat uses four main configuration files. Each controls a different aspect of the application, from environment variables to custom AI endpoints to Docker service overrides.
## Common Change Workflow
@@ -29,13 +29,13 @@ For example, to enable OpenRouter you add `OPENROUTER_KEY` to `.env`, add an Ope
-**`.env`** -- Server-level settings: API keys, database connection strings, feature flags, and authentication secrets. This is the primary configuration file for most deployments. See the [.env reference](/docs/configuration/dotenv) for all available variables.
+**`.env`**: Server-level settings: API keys, database connection strings, feature flags, and authentication secrets. This is the primary configuration file for most deployments. See the [.env reference](/docs/configuration/dotenv) for all available variables.
-**`librechat.yaml`** -- Custom AI endpoints, model settings, interface options, and advanced features like MCP servers and agents. This file is optional -- LibreChat works with defaults if it does not exist. See the [librechat.yaml guide](/docs/configuration/librechat_yaml) for setup instructions.
+**`librechat.yaml`**: Custom AI endpoints, model settings, interface options, and advanced features like MCP servers and agents. This file is optional. LibreChat works with defaults if it does not exist. See the [librechat.yaml guide](/docs/configuration/librechat_yaml) for setup instructions.
-**`docker-compose.yml`** -- Defines the Docker services (API server, database, search). Do not edit this file directly -- use an override file instead so your changes survive updates.
+**`docker-compose.yml`**: Defines the Docker services (`api`, `admin-panel`, `mongodb`, `meilisearch`, `vectordb`, and `rag_api`). Do not edit this file directly. Use an override file instead so your changes survive updates.
-**`docker-compose.override.yml`** -- Your local customizations to Docker services: volume mounts, port mappings, environment overrides. Docker Compose merges this with the main file automatically. See the [Docker override guide](/docs/configuration/docker_override).
+**`docker-compose.override.yml`**: Your local customizations to Docker services: volume mounts, port mappings, environment overrides. Docker Compose merges this with the main file automatically. See the [Docker override guide](/docs/configuration/docker_override).
## Applying Changes
diff --git a/content/docs/configuration/langfuse.mdx b/content/docs/configuration/langfuse.mdx
index 5952b1f97..397aef180 100644
--- a/content/docs/configuration/langfuse.mdx
+++ b/content/docs/configuration/langfuse.mdx
@@ -63,6 +63,12 @@ Add the following values to your `.env` file when deployment operators should ow
'Deterministic trace-level sample rate from 0 to 1. Default: 1.',
'LANGFUSE_SAMPLE_RATE=1',
],
+ [
+ 'LANGFUSE_TRACING_ENVIRONMENT',
+ 'string',
+ 'Optional Langfuse environment name attached to feedback scores, so they match the environment of their traces. When unset, scores are sent without an environment.',
+ 'LANGFUSE_TRACING_ENVIRONMENT=production',
+ ],
]}
/>
@@ -293,7 +299,7 @@ docker compose up -d
### Conversation Trace Viewer
-Enable `interface.traceViewer.enabled: true` in `librechat.yaml` to let users inspect a sampled
+Enable [`interface.traceViewer.enabled: true`](/docs/configuration/librechat_yaml/object_structure/interface#traceviewer) in `librechat.yaml` to let users inspect a sampled
Langfuse trace for their own conversation as a model-and-tool waterfall. It requires a Langfuse
release with the v2 Observations API. The viewer does not appear for another user's conversation,
unsampled traces, or traces whose user identity does not use LibreChat's internal user ID.
diff --git a/content/docs/configuration/logging.mdx b/content/docs/configuration/logging.mdx
index 1368a753d..7c9d3b6ee 100644
--- a/content/docs/configuration/logging.mdx
+++ b/content/docs/configuration/logging.mdx
@@ -1,7 +1,7 @@
---
title: Logging System
icon: ScrollText
-description: This doc explains how to use the logging feature of LibreChat, which saves error and debug logs in the `/api/logs` folder. You can use these logs to troubleshoot issues, monitor your server, and report bugs. You can also disable debug logs if you want to save space.
+description: This doc explains how to use the logging feature of LibreChat, which saves error and debug logs in the `/api/logs` folder. You can use these logs to troubleshoot issues, monitor your server, and report bugs. Debug logs are written only when you opt in with DEBUG_LOGGING=true.
---
### General
@@ -34,7 +34,7 @@ LibreChat has central logging built into its backend (api).
-Error logs are saved by default. Debug logs are enabled by default but can be turned off if not desired.
+Error logs are saved by default. Debug log files are written only when `DEBUG_LOGGING=true`; the provided `.env.example` sets it to `true`, but if the variable is unset no debug file is created.
This allows you to monitor your server through external tools that inspect log files, such as **[the ELK stack](https://aws.amazon.com/what-is/elk-stack/)**.
@@ -43,20 +43,20 @@ Debug logs are essential for developer work and fixing issues. If you encounter
Errors logs are also saved in the same location: `./api/logs/error-%DATE%.log`. If you have meilisearch configured, there is a separate log file for this as well.
- Note: Logs are rotated on a 14-day basis, so you will generate one error log file, one debug log
- file, and one meiliSync log file per 14 days. Errors will also be present in debug log files as
- well, but provide stack traces and more detail in the error log files.
+ Log files rotate daily: a new file is started each day, and a file is also split once it reaches
+ 20 MB. Rotated files are gzip-compressed and kept for 14 days. Errors are also present in debug
+ log files, but the error log files provide stack traces and more detail.
### Setup
-- Toggle debug logs with the following environment variable. By default, even if you never set this variable, debug logs will be generated, but you have the option to disable them by setting it to `FALSE`.
+- Debug log files are written only when this variable is set to `true`. If it is unset or set to anything else, no debug file is created.
-> Note: it's recommended to disable debug logs in a production environment.
+> Note: it's recommended to leave debug logs disabled in a production environment.
- For verbose server output in the console/terminal, you can set the following to `TRUE`:
@@ -99,6 +99,40 @@ By default, the JSON string length is truncated to 255 characters. You can confi
]}
/>
+- Console verbosity can be set with `CONSOLE_LOG_LEVEL` (`error`, `warn`, `info`, `http`, `verbose`, `debug`, `activity`, `silly`, or `silent`). `silent` turns off console output without disabling file logging. Invalid values fall back to the default with a warning.
+
+
+
+- Debug log messages are truncated to 150 characters by default, and log redaction is bounded to 5000 values per record. Tune these with `DEBUG_MESSAGE_LENGTH` and `LOG_REDACTION_MAX_NODES`.
+
+
+
+- To write log files somewhere other than the default location, set `LIBRECHAT_LOG_DIR`. See [Logging](/docs/configuration/dotenv#logging) in the `.env` reference.
+
- File-backed log transports are enabled by default. Set `LOG_TO_FILE=false` if your deployment should only emit logs to stdout/stderr.
-**Add the search variables to `.env`.** The Compose file sets `MEILI_HOST` to the internal service address for the `api` container, so you don't set the host here. Keep the master key identical to the one the `meilisearch` service uses.
+**Add the search variables to `.env`.** The Compose file sets `MEILI_HOST` to the internal service address for the `api` container, so you don't set the host here. The bundled `meilisearch` service reads `MEILI_MASTER_KEY` from this same file, so LibreChat and Meilisearch use the same key without any override.
```bash filename=".env"
SEARCH=true
@@ -40,21 +40,7 @@ MEILI_MASTER_KEY=
-**Pass the master key to the Meilisearch service.** The bundled `meilisearch` service does not read `.env`, so add it through `docker-compose.override.yml`. This keeps both LibreChat and Meilisearch using the same key.
-
-```yaml filename="docker-compose.override.yml"
-services:
- meilisearch:
- environment:
- - MEILI_MASTER_KEY=${MEILI_MASTER_KEY}
-```
-
-See [Docker Override](/docs/configuration/docker_override) for how override files are merged.
-
-
-
-
-**Start the stack.** Compose merges the override automatically and starts Meilisearch alongside LibreChat.
+**Start the stack.** Compose starts Meilisearch alongside LibreChat.
```bash filename="terminal"
docker compose up -d
@@ -177,7 +163,7 @@ If Meilisearch data is deleted or corrupted, or LibreChat treats everything as s
npm run reset-meili-sync
# Docker (default setup)
-docker compose exec api npm run reset-meili-sync
+docker compose exec -it api npm run reset-meili-sync
# Docker (deployment setup)
docker exec -it LibreChat-API /bin/sh -c "cd .. && npm run reset-meili-sync"
@@ -191,7 +177,7 @@ docker exec -it LibreChat-API /bin/sh -c "cd .. && npm run reset-meili-sync"
-The script resets the `_meiliIndex` flag to `false` for all messages and conversations in MongoDB, then reports how many documents were reset and how many remain to be synced.
+The script asks for confirmation (`y/N`) before changing anything, so run it in an interactive terminal. It resets the `_meiliIndex` flag to `false` for all messages and conversations in MongoDB, then reports how many documents were reset and how many remain to be synced.
**When to use it:**
@@ -204,6 +190,6 @@ The script resets the `_meiliIndex` flag to `false` for all messages and convers
| Variable | Default | Description |
| --- | --- | --- |
-| `MEILI_SYNC_BATCH_SIZE` | `100` | Number of documents synced per batch. |
-| `MEILI_SYNC_DELAY_MS` | `100` | Delay between sync batches, in milliseconds. |
+| `MEILI_SYNC_BATCH_SIZE` | `100` | Number of documents synced per batch. The reset script also uses this value for the size of its flag-reset batches, defaulting to `1000` there. |
+| `MEILI_SYNC_DELAY_MS` | `100` | Delay between sync batches, in milliseconds. Also used between the reset script's batches. |
| `MEILI_SYNC_THRESHOLD` | `1000` | Minimum number of unsynced documents before a sync is triggered. |
diff --git a/content/docs/configuration/metrics.mdx b/content/docs/configuration/metrics.mdx
index 7be0eb9bc..99b214de2 100644
--- a/content/docs/configuration/metrics.mdx
+++ b/content/docs/configuration/metrics.mdx
@@ -26,6 +26,31 @@ scrape_configs:
- targets: ['librechat.example.com']
```
+### Process, HTTP, and Request Metrics
+
+The endpoint also exposes the default Node.js and process metrics from `prom-client`, plus the following series.
+
+| Group | Metric | Labels |
+| --- | --- | --- |
+| HTTP | `http_requests_total`, `http_request_duration_seconds` | `method`, `path`, `status` |
+| HTTP | `http_requests_in_flight`, `http_request_body_bytes` (from `Content-Length`) | `method`, `path` |
+| SSE | `sse_streams_total`, `sse_stream_duration_seconds` | `method`, `path`, `status` |
+| SSE | `sse_streams_in_flight` | `method`, `path` |
+| Uploads | `upload_requests_total`, `upload_request_duration_seconds` | `method`, `path`, `status` |
+| Uploads | `upload_requests_in_flight`, `upload_bytes_total` (from `Content-Length`) | `method`, `path` |
+| OpenID | `openid_user_lookup_total`, `openid_user_lookup_duration_seconds` | `result` |
+| Mongoose | `mongoose_queries_total`, `mongoose_query_duration_seconds` | `model`, `operation`, `status` |
+| Generation jobs | `generation_jobs_total` | `store`, `result` |
+| Generation jobs | `generation_jobs_in_flight` | `store` |
+| Generation streams | `generation_stream_subscriptions_total` | `store`, `type`, `result` |
+| Generation streams | `generation_stream_resume_pending_events_total`, `generation_stream_early_buffer_overflows_total`, `generation_stream_first_attachment_delay_seconds` | `store` |
+| Generation streams | `generation_stream_attachment_outcomes_total` | `store`, `outcome` |
+| Generation streams | `generation_stream_recoveries_total`, `generation_stream_recovery_duration_seconds`, `generation_stream_recovery_events`, `generation_stream_recovery_content_parts` | `store`, `method`, `outcome` |
+| Content filter | `content_filter_locator_traversal_failures_total` | `operation`, `reason` |
+| Content filter | `content_filter_locator_traversal_size` | `operation`, `reason`, `dimension` |
+
+The generation stream recovery metrics describe how an early event buffer that overflowed is reconstructed. The content filter metrics count incomplete resolved file locator traversals.
+
### Agent Startup Metrics
Initial Agent chat requests emit two startup metrics:
@@ -35,7 +60,7 @@ Initial Agent chat requests emit two startup metrics:
Milestones cover request admission, job creation and acknowledgement, conversation and history loading, client and run initialization, stream startup, and the first queued response or content event. Results distinguish content queued, completion without a content delta, deduplication, rejection, pause, replacement, abort, and error.
-When [backend OpenTelemetry tracing](/docs/configuration/dotenv#opentelemetry-tracing) is enabled, the `librechat.agent.startup` span reports the same milestones as events. It includes total startup duration, milestone count, terminal result, and the generation stream ID when one is assigned.
+When [backend OpenTelemetry tracing](/docs/configuration/dotenv#opentelemetry-traces-and-logs) is enabled, the `librechat.agent.startup` span reports the same milestones as events. It includes total startup duration, milestone count, terminal result, and the generation stream ID when one is assigned.
### Redis Metrics
@@ -46,7 +71,7 @@ Redis-backed caches and services emit two logical-operation metrics:
`client` is `keyv` or `ioredis`, and `status` is `success` or `error`. Bounded `use_case` labels identify work such as caches, sessions, rate limits, concurrency, ACL principals, resumable stream jobs and pub/sub, MCP registry scans, and leader election. These metrics count LibreChat's logical operations rather than every internal Redis round trip. Connection lifecycle pings and global maintenance are excluded, and clearing a namespace is counted as one logical operation.
-When [backend OpenTelemetry tracing](/docs/configuration/dotenv#opentelemetry-tracing) is enabled, each HTTP span also summarizes its Redis work with:
+When [backend OpenTelemetry tracing](/docs/configuration/dotenv#opentelemetry-traces-and-logs) is enabled, each HTTP span also summarizes its Redis work with:
- `librechat.redis.calls`
- `librechat.redis.duration_ms`
diff --git a/content/docs/configuration/mod_system.mdx b/content/docs/configuration/mod_system.mdx
index 1900944fa..4a78a61c8 100644
--- a/content/docs/configuration/mod_system.mdx
+++ b/content/docs/configuration/mod_system.mdx
@@ -36,13 +36,13 @@ The following are all of the related env variables to make use of and configure
['CONCURRENT_VIOLATION_SCORE', 'integer', 'Score for concurrent violations.','CONCURRENT_VIOLATION_SCORE=1'],
['MESSAGE_VIOLATION_SCORE', 'integer', 'Score for message violations.','MESSAGE_VIOLATION_SCORE=1'],
['NON_BROWSER_VIOLATION_SCORE', 'integer', 'Score for non-browser violations.','NON_BROWSER_VIOLATION_SCORE=20'],
- ['IMPORT_VIOLATION_SCORE', 'integer', 'Score for import conversation violations.','IMPORT_VIOLATION_SCORE=1'],
- ['FORK_VIOLATION_SCORE', 'integer', 'Score for conversation fork violations.','FORK_VIOLATION_SCORE=1'],
+ ['IMPORT_VIOLATION_SCORE', 'integer', 'Score for import conversation violations. Defaults to 1 when unset.','IMPORT_VIOLATION_SCORE=1'],
+ ['FORK_VIOLATION_SCORE', 'integer', 'Score for conversation fork violations. Defaults to 1 when unset.','FORK_VIOLATION_SCORE=1'],
['TTS_VIOLATION_SCORE', 'integer', 'Score for text-to-speech violations.','TTS_VIOLATION_SCORE=0'],
['STT_VIOLATION_SCORE', 'integer', 'Score for speech-to-text violations.','STT_VIOLATION_SCORE=0'],
['FILE_UPLOAD_VIOLATION_SCORE', 'integer', 'Score for file upload violations.','FILE_UPLOAD_VIOLATION_SCORE=0'],
- ['RESET_PASSWORD_VIOLATION_SCORE', 'integer', 'Score for password reset violations.','RESET_PASSWORD_VIOLATION_SCORE=0'],
- ['VERIFY_EMAIL_VIOLATION_SCORE', 'integer', 'Score for email verification violations.','VERIFY_EMAIL_VIOLATION_SCORE=0'],
+ ['RESET_PASSWORD_VIOLATION_SCORE', 'integer', 'Score for password reset violations.','RESET_PASSWORD_VIOLATION_SCORE=1'],
+ ['VERIFY_EMAIL_VIOLATION_SCORE', 'integer', 'Score for email verification violations.','VERIFY_EMAIL_VIOLATION_SCORE=1'],
['TOOL_CALL_VIOLATION_SCORE', 'integer', 'Score for tool call violations.','TOOL_CALL_VIOLATION_SCORE=0'],
['CONVO_ACCESS_VIOLATION_SCORE', 'integer', 'Score for conversation access violations.','CONVO_ACCESS_VIOLATION_SCORE=0'],
]}
@@ -123,17 +123,14 @@ These can also be set under [`rateLimits.emailChange` and `rateLimits.emailChang
### Import conversation rate limiting
-Limits how often users can import conversations to prevent abuse.
-
-> Note: You can utilize both limiters, but default is to limit by IP only.
+Limits how often users can import conversations to prevent abuse. The per-IP and per-user limiters are always active; tune them with the variables below.
#### Import conversation rate limiting (per IP)
@@ -141,23 +138,19 @@ Limits how often users can import conversations to prevent abuse.
### Conversation forking rate limiting
-Limits how often users can fork conversations to prevent abuse.
-
-> Note: You can utilize both limiters, but default is to limit by IP only.
+Limits how often users can fork conversations to prevent abuse. The per-IP and per-user limiters are always active; tune them with the variables below.
#### Conversation forking rate limiting (per IP)
+### Other limiters
+
+The share link (`SHARE_*`), file usage (`FILE_USAGE_*`), password reset (`RESET_PASSWORD_*`), and email verification (`VERIFY_EMAIL_*`) limiters have their own variables, which are listed in the [.env reference](/docs/configuration/dotenv).
+
#### Illegal model requests
> Note: Illegal model requests are almost always nefarious as it means a 3rd party is attempting to access the server through an automated script. For this, I recommend a relatively high score, no less than 5.
@@ -187,7 +183,7 @@ Limits how often users can fork conversations to prevent abuse.
diff --git a/content/docs/configuration/pre_configured_ai/bedrock.mdx b/content/docs/configuration/pre_configured_ai/bedrock.mdx
index 236b3cba4..471b84833 100644
--- a/content/docs/configuration/pre_configured_ai/bedrock.mdx
+++ b/content/docs/configuration/pre_configured_ai/bedrock.mdx
@@ -73,22 +73,43 @@ BEDROCK_AWS_SECRET_ACCESS_KEY=your_secret_access_key
# BEDROCK_AWS_SESSION_TOKEN=your_session_token
```
+To let users provide their own credentials from the LibreChat UI, set `BEDROCK_AWS_ACCESS_KEY_ID`, `BEDROCK_AWS_SECRET_ACCESS_KEY`, or `BEDROCK_AWS_SESSION_TOKEN` to `user_provided`. Each variable set to `user_provided` is taken from the user's stored key instead of the environment.
+
+```bash filename=".env"
+BEDROCK_AWS_DEFAULT_REGION=us-east-1
+BEDROCK_AWS_ACCESS_KEY_ID=user_provided
+BEDROCK_AWS_SECRET_ACCESS_KEY=user_provided
+BEDROCK_AWS_SESSION_TOKEN=user_provided
+```
+
If `BEDROCK_AWS_ACCESS_KEY_ID` and `BEDROCK_AWS_SECRET_ACCESS_KEY` are set, LibreChat passes them directly to the Bedrock client. They must be provided together, and they take precedence over `BEDROCK_AWS_PROFILE` and the SDK default provider chain for Bedrock.
If `BEDROCK_AWS_BEARER_TOKEN` is set, LibreChat uses bearer auth for Bedrock instead of static credentials, `BEDROCK_AWS_PROFILE`, or the SDK default provider chain.
For AWS credential behavior details, see the [AWS SDK for JavaScript credential provider chain](https://docs.aws.amazon.com/sdk-for-javascript/v3/developer-guide/setting-credentials-node.html), the [AWS SDKs and Tools settings reference](https://docs.aws.amazon.com/sdkref/latest/guide/settings-reference.html), and the [AWS `credential_process` security notes](https://docs.aws.amazon.com/cli/latest/userguide/cli-configure-sourcing-external.html).
+### Reverse proxy
+
+To route Bedrock API calls through a custom endpoint, set `BEDROCK_REVERSE_PROXY` to the host name. LibreChat sends requests to `https://` followed by this value. It works with or without the `PROXY` setting.
+
+```bash filename=".env"
+BEDROCK_REVERSE_PROXY=bedrock-proxy.example.com
+```
+
## Configuring models
- You can optionally specify which models you want to make available with `BEDROCK_AWS_MODELS`:
```bash filename=".env"
-BEDROCK_AWS_MODELS=global.anthropic.claude-fable-5-1,global.anthropic.claude-fable-5,global.anthropic.claude-opus-5,global.anthropic.claude-opus-4-8,global.anthropic.claude-opus-4-7,global.anthropic.claude-sonnet-5,global.anthropic.claude-sonnet-4-6,meta.llama3-1-8b-instruct-v1:0
+BEDROCK_AWS_MODELS=global.anthropic.claude-fable-5-1,global.anthropic.claude-fable-5,global.anthropic.claude-opus-5-5,global.anthropic.claude-opus-5,global.anthropic.claude-sonnet-5-5,global.anthropic.claude-opus-4-8,global.anthropic.claude-opus-4-7,global.anthropic.claude-sonnet-5,global.anthropic.claude-sonnet-4-6,global.anthropic.claude-haiku-5-5,meta.llama3-1-8b-instruct-v1:0
```
If omitted, LibreChat includes its known supported models automatically. Claude 4 and newer defaults use Bedrock cross-region inference profile IDs because their bare `anthropic.` foundation-model IDs do not support on-demand Converse requests. LibreChat uses `global.` profiles where available and `us.` for Claude Opus 4.1. Use `BEDROCK_AWS_MODELS` to select a different profile available to your account.
+- The default Bedrock catalog also includes Claude Opus 5.5 (`global.anthropic.claude-opus-5-5`), Claude Sonnet 5.5 (`global.anthropic.claude-sonnet-5-5`), and Claude Haiku 5.5 (`global.anthropic.claude-haiku-5-5`).
+
+- You can also set the list in `librechat.yaml` with `endpoints.bedrock.models`, which replaces `BEDROCK_AWS_MODELS`.
+
- Claude Fable/Mythos-class models on Bedrock are inference-profile only. Use a profile ID such as `global.anthropic.claude-fable-5-1`, and enable Anthropic data sharing in the Bedrock console or Data Retention API before invoking them. Fable 5.1 has a 1M-token context window, 128K-token maximum output, adaptive thinking, and prompt-cache support.
- Claude Opus 5 has a 1M-token context window and 128K-token maximum output. Adaptive thinking is enabled unless explicitly disabled. When thinking is disabled, LibreChat limits `xhigh` or `max` effort to `high` so Bedrock accepts the request.
diff --git a/content/docs/configuration/pre_configured_ai/google.mdx b/content/docs/configuration/pre_configured_ai/google.mdx
index 2284bedaa..dca0e7616 100644
--- a/content/docs/configuration/pre_configured_ai/google.mdx
+++ b/content/docs/configuration/pre_configured_ai/google.mdx
@@ -45,9 +45,11 @@ Since fetching the models list isn't yet supported, you should set the models yo
For example, the following current models can be configured for the Gemini API:
```bash filename=".env"
-GOOGLE_MODELS=gemini-3.8-flash,gemini-3.7-flash,gemini-3.6-flash,gemini-3.5-flash,gemini-3.5-flash-lite,gemini-3.1-pro-preview,gemini-3.1-pro-preview-customtools,gemini-3.1-flash-lite-preview,gemini-2.5-pro,gemini-2.5-flash,gemini-2.5-flash-lite,gemini-2.0-flash,gemini-2.0-flash-lite
+GOOGLE_MODELS=gemini-4-argon,gemini-3.8-flash,gemini-3.7-flash,gemini-3.6-flash,gemini-3.5-flash,gemini-3.5-flash-lite,gemini-3.1-pro-preview,gemini-3.1-pro-preview-customtools,gemini-3.1-flash-lite-preview,gemini-2.5-pro,gemini-2.5-flash,gemini-2.5-flash-lite,gemini-2.0-flash,gemini-2.0-flash-lite
```
+You can also set the list in `librechat.yaml` with `endpoints.google.models`, an array of model IDs. A list configured there replaces `GOOGLE_MODELS`. It is read from the configuration resolved for each request, so a configuration override applied to a role or group can narrow it for those users.
+
- Gemini 3.8 Flash, Gemini 3.7 Flash, Gemini 3.6 Flash, Gemini 3.5 Flash, and Gemini 3.5 Flash-Lite are supported through both Google AI Studio and Google Cloud Gemini Enterprise Agent Platform. LibreChat assigns each a 1,048,576-token context window; Gemini 3.8 Flash supports up to 65,536 output tokens.
@@ -160,7 +162,8 @@ This is particularly useful for features that require Vertex AI authentication,
You can also specify the Google Cloud location for Vertex AI API requests:
```bash filename=".env"
-# Google Cloud region for Vertex AI
+# Google Cloud region for Vertex AI (defaults to us-central1)
+# The multi-region locations us, eu, and global are also accepted.
GOOGLE_LOC=us-central1
# Alternative region for Gemini Image Generation (defaults to global)
@@ -172,17 +175,17 @@ Since fetching the models list isn't yet supported, you should set the models yo
For Vertex AI, use the Vertex model IDs where they differ from the Gemini API:
```bash filename=".env"
-GOOGLE_MODELS=gemini-3.8-flash,gemini-3.7-flash,gemini-3.6-flash,gemini-3.5-flash,gemini-3.5-flash-lite,gemini-3.1-pro-preview,gemini-3.1-pro-preview-customtools,gemini-3.1-flash-lite-preview,gemini-2.5-pro,gemini-2.5-flash,gemini-2.5-flash-lite,gemini-2.0-flash-001,gemini-2.0-flash-lite-001
+GOOGLE_MODELS=gemini-4-argon,gemini-3.8-flash,gemini-3.7-flash,gemini-3.6-flash,gemini-3.5-flash,gemini-3.5-flash-lite,gemini-3.1-pro-preview,gemini-3.1-pro-preview-customtools,gemini-3.1-flash-lite-preview,gemini-2.5-pro,gemini-2.5-flash,gemini-2.5-flash-lite,gemini-2.0-flash-001,gemini-2.0-flash-lite-001
```
+On Vertex AI, `gemini-4-argon` is served only from the `global`, `us`, and `eu` multi-region endpoints, not from regional locations such as `us-central1`. With `GOOGLE_LOC` unset, LibreChat uses `global` for this model. If `GOOGLE_LOC` is set to a `us-` or `europe-` region, LibreChat moves the request to the `us` or `eu` multi-region so the data stays in the same geography. A region outside `us` and `eu` is kept as configured, and the request will fail unless you set `GOOGLE_LOC` to `global`, `us`, or `eu`.
+
Saved Agents using the `vertexai` provider also use this shared Google model catalog in the Agent Builder and at runtime. If the deployment supplies an explicit `vertexai` model catalog, that provider-specific list takes precedence; otherwise `GOOGLE_MODELS` is used for Vertex AI selection and validation.
If you're using docker and want to provide the `auth.json` file, you will need to also mount the volume in docker-compose.override.yml
```yaml filename="docker-compose.override.yml"
-version: '3.4'
-
services:
api:
volumes:
@@ -211,7 +214,9 @@ You can also exclude safety settings by setting the following in your .env file,
GOOGLE_EXCLUDE_SAFETY_SETTINGS=true
```
-NOTE: You do not have access to the BLOCK_NONE setting by default.
+Categories you do not set are sent with the `HARM_BLOCK_THRESHOLD_UNSPECIFIED` threshold, which leaves the provider default in place. The exception is `GOOGLE_SAFETY_CIVIC_INTEGRITY`, which defaults to `BLOCK_NONE` when unset.
+
+NOTE: Your Google account does not have access to the `BLOCK_NONE` setting by default, so requests can be rejected if it is sent (for example through the civic integrity default). In that case set `GOOGLE_SAFETY_CIVIC_INTEGRITY` to another threshold, or set `GOOGLE_EXCLUDE_SAFETY_SETTINGS=true`.
To use this restricted `HarmBlockThreshold` setting, you will need to either:
- (a) Get access through an allowlist via your Google account team
diff --git a/content/docs/configuration/pre_configured_ai/openai.mdx b/content/docs/configuration/pre_configured_ai/openai.mdx
index ef543fb9f..8e710b59a 100644
--- a/content/docs/configuration/pre_configured_ai/openai.mdx
+++ b/content/docs/configuration/pre_configured_ai/openai.mdx
@@ -33,7 +33,18 @@ Until a user sets a key, the endpoint is visible but unusable for them.
- When `OPENAI_API_KEY` is set to the actual API key value → as long as `OPENAI_MODELS` is left commented-out, it will do an API call to find out what models are available, which should include any new ones
```bash filename=".env"
-OPENAI_MODELS=gpt-6.1-sol,gpt-6-sol,gpt-6-luna,gpt-6-astra,gpt-5.6,gpt-5.6-terra,gpt-5.6-luna,gpt-5.5,gpt-5.5-pro,chat-latest,gpt-5.4,gpt-5.4-pro,gpt-5.4-mini,gpt-5.4-nano,gpt-5.3-codex,gpt-5.2,gpt-5,gpt-5-codex,gpt-5-mini,gpt-5-nano,o3-pro,o3,o4-mini,gpt-4.1,gpt-4.1-mini,gpt-4.1-nano,o3-mini,o1-pro,o1,gpt-4o,gpt-4o-mini
+OPENAI_MODELS=gpt-6-astra,gpt-6.1-sol,gpt-6-sol,gpt-6-luna,gpt-5.6,gpt-5.6-terra,gpt-5.6-luna,gpt-5.5,gpt-5.5-pro,chat-latest,gpt-5.4,gpt-5.4-pro,gpt-5.4-mini,gpt-5.4-nano,gpt-5.3-codex,gpt-5.2,gpt-5,gpt-5-codex,gpt-5-mini,gpt-5-nano,o3-pro,o3,o4-mini,gpt-4.1,gpt-4.1-mini,gpt-4.1-nano,o3-mini,o1-pro,o1,gpt-4o,gpt-4o-mini
+```
+
+You can also set the list in `librechat.yaml` with `endpoints.openAI.models`, an array of model IDs. A list configured there replaces `OPENAI_MODELS` and skips the API call that discovers models. The list is read from the configuration resolved for each request, so a configuration override applied to a role or group can narrow it for those users.
+
+```yaml filename="librechat.yaml"
+endpoints:
+ openAI:
+ models:
+ - gpt-6-astra
+ - gpt-5.6
+ - gpt-4o
```
**Notes:**
diff --git a/content/docs/configuration/rag_api.mdx b/content/docs/configuration/rag_api.mdx
index cccc3189d..0ecc45612 100644
--- a/content/docs/configuration/rag_api.mdx
+++ b/content/docs/configuration/rag_api.mdx
@@ -18,12 +18,29 @@ OpenAI Assistants have their own RAG implementation through the "Retrieval" capa
## Docker Quick Start
-For Docker, the RAG API is already wired up in both the default `docker-compose.yml` and `deploy-compose.yml` files, including the `RAG_API_URL` value. You only need to make sure you are running the latest image and compose files. See the [Updating LibreChat guide for Docker](/docs/local/docker#update-librechat) if you are unsure how to update.
+For Docker, the RAG API is already wired up in both the default `docker-compose.yml` and `deploy-compose.yml` files, including the `RAG_API_URL` value. You only need to make sure you are running the latest image and compose files. See the [Updating LibreChat guide for Docker](/docs/local/docker#updating-librechat) if you are unsure how to update.
With the default Docker setup, the `.env` file is shared between LibreChat and the RAG API. Define the RAG variables in that same file. The full list lives in the [RAG API README](https://github.com/LibreChat-AI/rag-api/blob/main/README.md).
+The default `docker-compose.yml` and `deploy-compose.yml` files set `RAG_API_URL=http://rag_api:${RAG_PORT:-8000}` on the `api` service. Environment variables set on the service take precedence over the `.env` file, so you do not need to add `RAG_API_URL` to `.env` for the bundled setup, and setting it there has no effect. To point a Docker deployment at an external RAG API, override the value on the `api` service instead, for example for a RAG API running on the Docker host:
+
+```yaml filename="docker-compose.override.yml"
+services:
+ api:
+ environment:
+ - RAG_API_URL=http://host.docker.internal:8000
+ extra_hosts:
+ - "host.docker.internal:host-gateway"
+```
+
+The `extra_hosts` entry is needed on Linux, where Docker does not define `host.docker.internal` itself.
+
+Compose loads `docker-compose.override.yml` automatically only with the default `docker-compose.yml`. With `deploy-compose.yml`, pass both files: `docker compose -f deploy-compose.yml -f docker-compose.override.yml up -d`.
+
+Outside Docker, set `RAG_API_URL` in your `.env` file.
+
Pick the embeddings provider you want to use.
@@ -34,15 +51,6 @@ Pick the embeddings provider you want to use.
-**Set the RAG API URL.** Add the following to your `.env` file:
-
-```bash filename=".env"
-RAG_API_URL=http://host.docker.internal:8000
-```
-
-
-
-
**Provide an OpenAI API key (if needed).** If your OpenAI API key is set to `user_provided`, add a key for embeddings. Skip this step if you already supply the OpenAI key in your `.env` file.
```bash filename=".env"
@@ -72,7 +80,6 @@ docker compose up -d
**Configure the provider.** Add the following to your `.env` file:
```bash filename=".env"
-RAG_API_URL=http://host.docker.internal:8000
EMBEDDINGS_PROVIDER=huggingface
HF_TOKEN=hf_xxxxxxxxxxxxxxxxxxxxxxx
```
@@ -83,8 +90,6 @@ HF_TOKEN=hf_xxxxxxxxxxxxxxxxxxxxxxx
**Switch to the full RAG API image.** Update your `docker-compose.override.yml` file:
```yaml filename="docker-compose.override.yml"
-version: '3.4'
-
services:
rag_api:
image: registry.librechat.ai/librechat-ai/librechat-rag-api-dev:latest
@@ -117,7 +122,6 @@ You need Ollama and the `nomic-embed-text` embedding model. Pull it with `ollama
**Configure the provider.** Add the following to your `.env` file:
```bash filename=".env"
-RAG_API_URL=http://host.docker.internal:8000
EMBEDDINGS_PROVIDER=ollama
OLLAMA_BASE_URL=http://host.docker.internal:11434
EMBEDDINGS_MODEL=nomic-embed-text
@@ -129,8 +133,6 @@ EMBEDDINGS_MODEL=nomic-embed-text
**Switch to the full RAG API image.** Update your `docker-compose.override.yml` file:
```yaml filename="docker-compose.override.yml"
-version: '3.4'
-
services:
rag_api:
image: registry.librechat.ai/librechat-ai/librechat-rag-api-dev:latest
@@ -170,7 +172,7 @@ The default compose files store the pgvector/PostgreSQL data in the Docker-manag
A non-container setup is more hands-on. Follow the instructions in the [RAG API repo](https://github.com/LibreChat-AI/rag-api/).
-Set `RAG_API_URL` in your LibreChat `.env` file to wherever the API is reachable from your setup. This differs from Docker, where the value is already set in the default `docker-compose.yml` file.
+Set `RAG_API_URL` in your LibreChat `.env` file to wherever the API is reachable from your setup. This differs from the bundled Docker setup, where the value is already set on the `api` service in the default `docker-compose.yml` and `deploy-compose.yml` files.
## Configuration
@@ -180,7 +182,7 @@ Set RAG API options through environment variables in an `.env` file accessible t
Using an invalid key (e.g., the deprecated `STATIC_CONFIG`) will cause a startup error. Only use
@@ -325,6 +337,20 @@ The application uses a dual-client approach:
- **IoRedis client**: Primary Redis operations with automatic prefixing
- **Keyv Redis client**: Store-layer operations with prefix handling in `cacheFactory.js`
+### Advanced Connection Tuning
+
+These optional variables tune connection behavior and bulk cache operations. The defaults suit most deployments.
+
+| Variable | Default | Description |
+| --- | --- | --- |
+| `REDIS_CONNECT_TIMEOUT` | `10000` | Connection timeout in milliseconds. |
+| `REDIS_RETRY_MAX_ATTEMPTS` | `10` | Maximum reconnection attempts before giving up. `0` retries indefinitely. |
+| `REDIS_RETRY_MAX_DELAY` | `3000` | Maximum delay between reconnection attempts, in milliseconds. |
+| `REDIS_ENABLE_OFFLINE_QUEUE` | `true` | Queue commands while disconnected. Set to `false` to fail them immediately. |
+| `REDIS_SCAN_COUNT` | `1000` | `COUNT` hint for `SCAN` operations when finding keys by pattern. |
+| `REDIS_DELETE_CHUNK_SIZE` | `1000` | Number of keys deleted per batch in bulk deletes. |
+| `MCP_REGISTRY_CACHE_TTL` | `5000` | Milliseconds MCP registry caches are kept. Cross-instance staleness can reach twice this value. `0` disables the local snapshot, so every read goes to Redis. |
+
### Memory Optimization
Use `FORCED_IN_MEMORY_CACHE_NAMESPACES` to optimize performance by keeping frequently accessed, small datasets in memory while using Redis for larger caches.
@@ -350,7 +376,7 @@ REDIS_CA=/etc/ssl/redis-ca.pem
REDIS_KEY_PREFIX_VAR=DEPLOYMENT_ID
REDIS_MAX_LISTENERS=100
REDIS_PING_INTERVAL=300
-FORCED_IN_MEMORY_CACHE_NAMESPACES=ROLES,MESSAGES
+FORCED_IN_MEMORY_CACHE_NAMESPACES=CONFIG_STORE,APP_CONFIG,ROLES,MESSAGES
```
### Cluster Setup
@@ -369,7 +395,7 @@ Redis enables [Resumable Streams](/docs/features/resumable_streams) for horizont
**Important:** When `USE_REDIS=true`, resumable streams automatically use Redis for cross-instance coordination. This is the recommended setup for horizontally scaled deployments where users might connect to different server instances.
-**Note:** If you're running a single LibreChat instance, Redis for resumable streams is typically overkill—the built-in in-memory mode works fine. Redis becomes essential when you have multiple LibreChat instances behind a load balancer, where a user's reconnection might hit a different server than where their stream started.
+**Note:** If you're running a single LibreChat instance, Redis for resumable streams is typically overkill; the built-in in-memory mode works fine. Redis becomes essential when you have multiple LibreChat instances behind a load balancer, where a user's reconnection might hit a different server than where their stream started.
### Configuration
diff --git a/content/docs/configuration/stt_tts.mdx b/content/docs/configuration/stt_tts.mdx
index a6ea4336d..8441f2421 100644
--- a/content/docs/configuration/stt_tts.mdx
+++ b/content/docs/configuration/stt_tts.mdx
@@ -4,10 +4,6 @@ icon: Mic
description: Configuration of the Speech to Text (STT) and Text to Speech (TTS) features
---
-
-The Google Cloud STT/TTS and Deepgram services are being planned for future integration.
-
-
## Speech Introduction
The Speech Configuration includes settings for both Speech-to-Text (STT) and Text-to-Speech (TTS) under a unified `speech:` section. Additionally, there is a new `speechTab` menu for user-specific settings.
@@ -28,6 +24,10 @@ TTS_API_KEY=your-tts-api-key
These keys are then referenced in your `librechat.yaml` configuration using `${STT_API_KEY}` and `${TTS_API_KEY}`.
+### One provider per service
+
+Each of `speech.stt` and `speech.tts` takes at most one provider block, and either section can be left out to keep the browser engine for that service. If a section has more than one provider, requests fail with the error "Multiple providers are set. Please set only one provider."
+
### Self-hosted engines need an allowedAddresses entry
Both `speech.stt` and `speech.tts` accept an `allowedAddresses` list. Outbound speech requests are validated against their resolved IP and blocked from reaching private, loopback, and link-local address space, so a self-hosted engine on `localhost`, a LAN address, or a Docker service name is unreachable until you list it:
@@ -118,7 +118,7 @@ speech:
## STT (Speech-to-Text)
-The Speech-to-Text (STT) feature converts spoken words into written text. To enable STT, click on the STT button (near the send button) or use the key combination ++Ctrl+Alt+L++ to start the transcription.
+The Speech-to-Text (STT) feature converts spoken words into written text. To enable STT, click on the STT button (near the send button) or use the key combination ++Shift+Alt+L++ to start the transcription.
### Available STT Services
@@ -143,9 +143,12 @@ speech:
stt:
openai:
url: 'http://host.docker.internal:8080/v1/audio/transcriptions'
+ apiKey: '${STT_API_KEY}'
model: 'whisper'
```
+The `apiKey` field is required for every OpenAI-compatible STT block, including local ones. If your server does not check keys, use any placeholder value.
+
### Configuring Cloud STT
- #### OpenAI Whisper
@@ -180,7 +183,7 @@ You can specify either the full domain or just the instance name. If you provide
- #### OpenAI compatible
-Refer to the OpenAI Whisper section, adjusting the `url` and `model` as needed.
+Refer to the OpenAI Whisper section, adjusting the `url` and `model` as needed. The `apiKey` field is still required.
example
@@ -189,8 +192,9 @@ speech:
stt:
openai:
url: 'http://host.docker.internal:8080/v1/audio/transcriptions'
+ apiKey: '${STT_API_KEY}'
model: 'whisper'
- ```
+```
## TTS (Text-to-Speech)
@@ -209,6 +213,8 @@ The Text-to-Speech (TTS) feature converts written text into spoken words. Variou
- ElevenLabs
- Other OpenAI/ElevenLabs-compatible TTS services
+Text longer than `speech.tts.maxInputChars` (default 20000 characters) is truncated before it is read aloud. See the [Speech Object Structure](/docs/configuration/librechat_yaml/object_structure/speech) for details.
+
### Configuring Local TTS
- #### Browser-based
@@ -297,10 +303,10 @@ Additional ElevenLabs-specific parameters can be added as follows:
```yaml
voice_settings:
- similarity_boost: '' # number
- stability: '' # number
- style: '' # number
- use_speaker_boost: # boolean
+ similarity_boost: 0.75 # number
+ stability: 0.5 # number
+ style: 0 # number
+ use_speaker_boost: true # boolean
pronunciation_dictionary_locators: [''] # list of strings (array)
```
diff --git a/content/docs/configuration/token_usage.mdx b/content/docs/configuration/token_usage.mdx
index 8eb8ce587..79f10c423 100644
--- a/content/docs/configuration/token_usage.mdx
+++ b/content/docs/configuration/token_usage.mdx
@@ -61,7 +61,7 @@ endpoints:
context: 128000
```
-`prompt`, `completion`, and `context` are required for each model entry. `cacheRead` and `cacheWrite` can be added for providers that report cached input usage. For Agents that use multiple endpoints, LibreChat uses the matching endpoint/model token config when recording usage and cost.
+`prompt`, `completion`, and `context` are required for each model entry. `cacheRead`, `cacheWrite`, and `cacheWrite1h` (the one-hour cache write rate, which is twice `prompt` when omitted) can be added for providers that report cached input usage. For Agents that use multiple endpoints, LibreChat uses the matching endpoint/model token config when recording usage and cost.
Fetched token config is cached with user scope when endpoint models, keys, URLs, or headers can vary by request context, so isolated custom endpoint pricing and context windows stay separated.
@@ -104,6 +104,9 @@ balance:
refillIntervalValue: 30 # Numerical value for refill interval
refillIntervalUnit: 'days' # Time unit for refill interval (days, hours, etc.)
refillAmount: 10000 # Tokens added during each refill
+ refillMode: 'add' # 'add' or 'reset'
+ reservationTtlMs: 1800000 # How long an in-flight reservation counts against the balance
+ display: 'credits' # 'credits', 'currency', or 'percent'
```
### Balance Settings Explained
@@ -118,12 +121,20 @@ balance:
- **refillIntervalUnit**: Specifies the time unit for the refill interval. Supported values include "seconds", "minutes", "hours", "days", "weeks", and "months".
-- **refillAmount**: Specifies the number of tokens to be added to the user's balance during each automatic refill.
+- **refillAmount**: Specifies the number of tokens to be added to the user's balance during each automatic refill. With `refillMode: 'reset'`, it is the amount the balance is reset to.
+
+- **refillMode**: `add` (the default) adds `refillAmount` to the current balance. `reset` replaces the balance with `refillAmount` once the refill interval is due. `reset` requires `refillIntervalValue` to be a positive integer.
+
+- **reservationTtlMs**: How long, in milliseconds, an unreleased in-flight balance reservation keeps counting against the balance. Default: `1800000` (30 minutes). Minimum: `10000`.
+
+- **display**: How the UI presents the balance: `credits` (the default) shows the raw figure, `currency` shows its currency value, and `percent` shows the share of the period's allotment already spent.
Check out the [Balance Configuration](/docs/configuration/librechat_yaml/object_structure/balance) page for more details.
## How Auto-Refill Works
+The process below describes the default `add` mode. With `refillMode: 'reset'`, the balance is not topped up when it runs out. Instead, once the refill interval is due, the balance is replaced with `refillAmount` on the user's next balance read or request, so unused credits do not carry over.
+
When a user's balance is tracked and **autoRefill** is enabled, the system will automatically add credits to the balance only when the specified time interval has passed since the last refill. This is achieved by comparing the current date with the `lastRefill` date plus the specified interval.
### Auto-Refill Process
@@ -233,9 +244,9 @@ This works well to track your own usage for personal use; 1000 credits = $0.001
- With summarization enabled, you will be blocked from making an API request if the cost of the content that you need to summarize + your messages payload exceeds the current balance
- Subagent child-run model usage is recorded against the parent transaction so parent agent runs include delegated usage in their totals.
-- Counting Prompt tokens is really accurate for OpenAI calls, but not 100% for plugins (due to function calling). It is really close and conservative, meaning its count may be higher by 2-5 tokens.
+- Counting prompt tokens is accurate for OpenAI calls, but not exact when function calling is involved. It is close and conservative, meaning its count may be higher by 2-5 tokens.
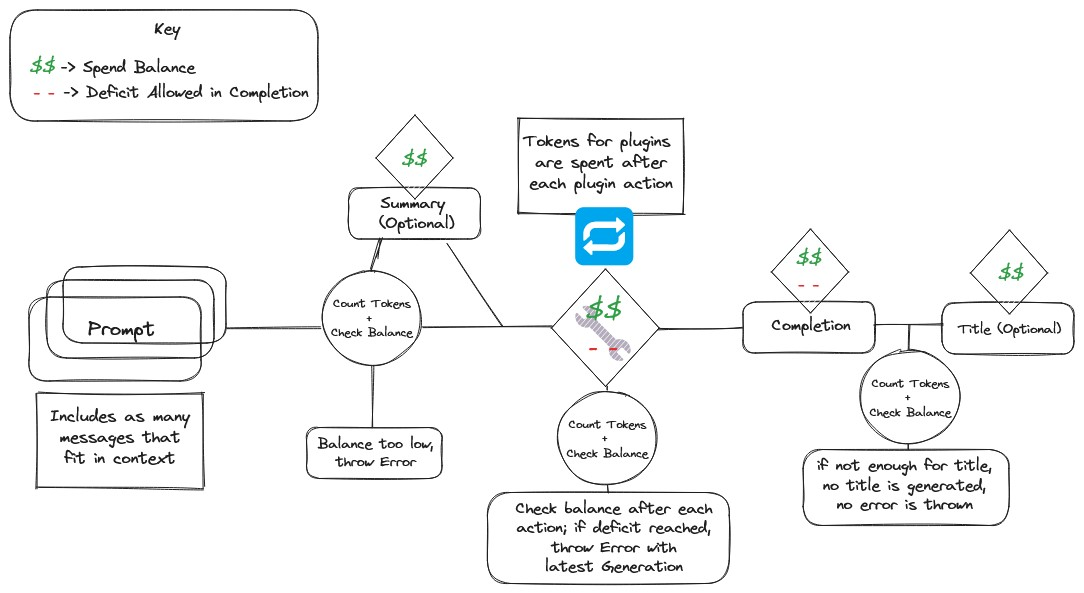
- The system allows deficits incurred by the completion tokens. It only checks if you have enough for the prompt Tokens, and is pretty lenient with the completion. The graph below details the logic
-- The above said, plugins are checked at each generation step, since the process works with multiple API calls. Anything the LLM has generated since the initial user prompt is shared to the user in the error message as seen below.
+- Runs that make multiple API calls, such as agents using tools, are checked at each generation step. Anything the LLM has generated since the initial user prompt is shared to the user in the error message as seen below.
- There is a 150 token buffer for titling since this is a 2 step process, that averages around 200 total tokens. In the case of insufficient funds, the titling is cancelled before any spend happens and no error is thrown.
diff --git a/content/docs/configuration/tools/azure_ai_search.mdx b/content/docs/configuration/tools/azure_ai_search.mdx
index b96ac1681..88fb2ed28 100644
--- a/content/docs/configuration/tools/azure_ai_search.mdx
+++ b/content/docs/configuration/tools/azure_ai_search.mdx
@@ -29,7 +29,7 @@ This is the name of the index to be searched (e.g., `hotels-sample-index`).
This is the authentication key to use when utilizing the search endpoint. Please issue it from the management console. Use the Value, not the name of the authentication key.
-# Introduction to tutorial
+## Introduction to tutorial
## Create or log in to your account on Azure Portal
@@ -130,7 +130,7 @@ AZURE_AI_SEARCH_SEARCH_OPTION_SELECT=field1, field2, field3
#### AZURE_AI_SEARCH_API_VERSION
-Specify the version of the search API. When using new features such as semantic search or vector search, you may need to specify the preview version. The default value is `2023-11-1`.
+Specify the version of the search API. When using new features such as semantic search or vector search, you may need to specify the preview version. The default value is `2023-11-01`.
#### AZURE_AI_SEARCH_SEARCH_OPTION_QUERY_TYPE
diff --git a/content/docs/configuration/tools/flux.mdx b/content/docs/configuration/tools/flux.mdx
index daafa17a1..4b557a846 100644
--- a/content/docs/configuration/tools/flux.mdx
+++ b/content/docs/configuration/tools/flux.mdx
@@ -15,6 +15,12 @@ Flux is a powerful image generation tool that can create high-quality images fro
FLUX_API_KEY=your_api_key_here
```
+Optionally, set `FLUX_API_BASE_URL` to use a different API base URL. It defaults to `https://api.us1.bfl.ai`.
+
+```bash
+FLUX_API_BASE_URL=https://api.us1.bfl.ai
+```
+
3. Restart LibreChat and add **Flux** to an agent's **Tools** list.
| Deployment | Command |
@@ -30,10 +36,9 @@ FLUX_API_KEY=your_api_key_here
- Customizable image dimensions
- Adjustable generation parameters
- Multiple endpoint options for different use cases
-- Batch generation support (up to 24 images)
### Available Endpoints
-- `/v1/flux-pro` - Standard endpoint (default)
+- `/v1/flux-pro` - Standard endpoint (default when no endpoint is specified)
- `/v1/flux-pro-1.1` - Enhanced version
- `/v1/flux-dev` - Development version
- `/v1/flux-pro-1.1-ultra` - Premium quality endpoint
@@ -49,28 +54,28 @@ The Flux tool supports three main actions:
For `generate` action:
-• **prompt** – Text description for the image (required)
-• **width** – Width in pixels (multiple of 32)
-• **height** – Height in pixels (multiple of 32)
-• **prompt_upsampling** – Whether to perform upsampling on the prompt (default: false)
-• **steps** – Number of diffusion steps (1-50, default: 40)
-• **seed** – Optional seed for reproducibility
-• **safety_tolerance** – Tolerance level for moderation (0-6, default: 6)
-• **endpoint** – Model endpoint to use:
- - `/v1/flux-pro-1.1` (default)
- - `/v1/flux-pro`
+• **prompt**: Text description for the image (required)
+• **width**: Width in pixels (multiple of 32)
+• **height**: Height in pixels (multiple of 32)
+• **prompt_upsampling**: Whether to perform upsampling on the prompt (default: false)
+• **steps**: Number of diffusion steps (1-50, default: 40)
+• **seed**: Optional seed for reproducibility
+• **safety_tolerance**: Tolerance level for moderation (0-6, default: 6)
+• **endpoint**: Model endpoint to use:
+ - `/v1/flux-pro` (default)
+ - `/v1/flux-pro-1.1`
- `/v1/flux-dev`
- `/v1/flux-pro-1.1-ultra`
-• **raw** – Generate less processed images (only for ultra endpoint, default: false)
+• **raw**: Generate less processed images (only for ultra endpoint, default: false)
For `generate_finetuned` action:
• All parameters from `generate` plus:
-• **finetune_id** – ID of the fine-tuned model (required)
-• **finetune_strength** – Strength of the fine-tuning effect (0.1-1.2, default: 1.1)
-• **guidance** – Guidance scale (default: 2.5)
-• **aspect_ratio** – Aspect ratio for ultra models (default: "16:9")
-• **endpoint** – Must be one of:
+• **finetune_id**: ID of the fine-tuned model (required)
+• **finetune_strength**: Strength of the fine-tuning effect (typically 0.1-1.2, default: 1.0)
+• **guidance**: Guidance scale (default: 2.5)
+• **aspect_ratio**: Aspect ratio for ultra models (for example, "16:9")
+• **endpoint**: Must be one of:
- `/v1/flux-pro-finetuned` (default)
- `/v1/flux-pro-1.1-ultra-finetuned`
@@ -106,7 +111,6 @@ For `generate_finetuned` action:
- Seamless integration with chat interfaces
- Markdown-formatted output
- Built-in error handling and logging
-- Support for batch processing
## Usage Examples
@@ -125,6 +129,5 @@ Common error messages and solutions:
## Rate Limits and Usage
-- Free tier includes generous usage limits
-- Multiple images can be generated in a single request
+- Usage limits and pricing depend on your Black Forest Labs account
- Consider using lower step counts for faster generations during testing
diff --git a/content/docs/configuration/tools/gemini_image_gen.mdx b/content/docs/configuration/tools/gemini_image_gen.mdx
index c0fc9884c..465febd08 100644
--- a/content/docs/configuration/tools/gemini_image_gen.mdx
+++ b/content/docs/configuration/tools/gemini_image_gen.mdx
@@ -76,8 +76,10 @@ GEMINI_IMAGE_MODEL=gemini-3-pro-image-preview
The Gemini Image Gen tool accepts the following parameters:
-- **prompt** (required) – A detailed text description of the desired image, up to 32,000 characters
-- **image_ids** (optional) – Array of image IDs to use as visual context for generation
+- **prompt** (required): A detailed text description of the desired image, up to 32,000 characters
+- **image_ids** (optional): Array of image IDs to use as visual context for generation
+- **aspectRatio** (optional): The shape of the image. One of `1:1`, `2:3`, `3:2`, `3:4`, `4:3`, `4:5`, `5:4`, `9:16`, `16:9`, or `21:9`. Defaults to `1:1` when omitted.
+- **imageSize** (optional): The resolution of the image. One of `1K`, `2K`, or `4K`. Defaults to `1K` when omitted. It is ignored when the model is `gemini-2.5-flash-image`.
## Best Practices
@@ -101,7 +103,7 @@ When editing existing images:
- "Remove the background from this image"
- "Add sunglasses to the person in this image"
- "Change the color of the car to red"
-3. **Don't reconstruct the original prompt** – use simple, direct modification instructions
+3. **Don't reconstruct the original prompt**: use simple, direct modification instructions
## Usage Examples
@@ -145,7 +147,7 @@ Gemini includes built-in safety filters. If your image is blocked:
### Storage Integration
-Generated images are automatically saved using your configured file strategy (local, S3, Azure, or Firebase). This is handled by the framework — the tool returns image data and the agent callback system persists it as a message attachment.
+Generated images are automatically saved using your configured file strategy (local, S3, Azure, or Firebase). This is handled by the framework: the tool returns image data and the agent callback system persists it as a message attachment.
### Image Format
diff --git a/content/docs/configuration/tools/google_search.mdx b/content/docs/configuration/tools/google_search.mdx
index 7ac2c5fab..14e687ee8 100644
--- a/content/docs/configuration/tools/google_search.mdx
+++ b/content/docs/configuration/tools/google_search.mdx
@@ -64,7 +64,7 @@ GOOGLE_CSE_ID=your-search-engine-id-here
### Add the Tool to an Agent
-In LibreChat, go to the **Agents** panel and create or edit an agent. In the agent's **Tools** list, select **Google Search**.
+In LibreChat, go to the **Agents** panel and create or edit an agent. In the agent's **Tools** list, select **Google** (the tool is listed under this name in the Agent Builder).
diff --git a/content/docs/configuration/tools/index.mdx b/content/docs/configuration/tools/index.mdx
index 228c7b033..b156e5bc1 100644
--- a/content/docs/configuration/tools/index.mdx
+++ b/content/docs/configuration/tools/index.mdx
@@ -72,6 +72,8 @@ Start a chat with that agent and ask for something that requires the tool, such
| OpenWeather | Current, forecast, historical, and daily weather data | `OPENWEATHER_API_KEY` | [OpenWeather](/docs/configuration/tools/openweather) |
| Wolfram\|Alpha | Math, computation, units, curated knowledge, and real-time data | `WOLFRAM_APP_ID` | [Wolfram\|Alpha](/docs/configuration/tools/wolfram) |
| Calculator | Basic and complex calculations | None | [Calculator](/docs/configuration/tools/calculator) |
+| GitHub Compare (agents only) | Compare commit ancestry in a public GitHub repository without a workspace | `githubCompare.enabled: true` in `librechat.yaml` (disabled by default); optional `githubCompare.timeoutMs` (default 10000, maximum 30000) | None |
+| Ask User (agents only) | Let the agent pause mid-run to ask a clarifying question and wait for the answer | None | None |
## Creating Custom Tools
diff --git a/content/docs/configuration/tools/openweather.mdx b/content/docs/configuration/tools/openweather.mdx
index bb150b272..a5d786a19 100644
--- a/content/docs/configuration/tools/openweather.mdx
+++ b/content/docs/configuration/tools/openweather.mdx
@@ -44,6 +44,7 @@ In LibreChat, select **Agents**, create or edit an agent, open the agent's **Too
The OpenWeather tool supports the following actions:
+- `help`: Return guidance on the available actions and their parameters
- `current_forecast`: Get current weather and forecast data
- `timestamp`: Get historical weather data for a specific date
- `daily_aggregation`: Get aggregated weather data for a specific date
@@ -63,6 +64,7 @@ What's the temperature in New York in Fahrenheit?
- `city`: Name of the city (if lat/lon not provided)
- `lat`: Latitude coordinate (optional if city provided)
- `lon`: Longitude coordinate (optional if city provided)
+- `exclude`: Comma-separated parts of the response to leave out (used by the current_forecast action)
- `units`: Temperature units ("Celsius", "Kelvin", or "Fahrenheit")
- `lang`: Language code for weather descriptions (e.g., "en", "fr", "es")
- `date`: Date in YYYY-MM-DD format (required for timestamp and daily_aggregation actions)